OpenKruise Agents v0.6.0: Making Agent Sandboxes Safer, Easier to Operate, and More Resource-Efficient

· 22 min read

Keywords: L4/L7 Traffic Control · Credential Injection · CheckpointRestore · PoolAutoscaler · Auto Pause/Resume

The v0.3.0 release answered one question: once a Sandbox is handed to an Agent, how do you upgrade it, resize it, and account for it. Its roadmap closed with two promises — TrafficPolicy / SecurityProfile for network governance, and a security identity integration that keeps platform credentials out of Agent code.

OpenKruise Agents v0.6.0 delivers both, and adds the operational machinery around them: 283 merged pull requests since v0.3.0. The four capabilities this post covers in depth are:

  • Layer 4 and Layer 7 network access control plus token management — TrafficPolicy for destination reachability, SecurityProfile for per-request inspection, MCP tool-level ACLs, credential injection from Kubernetes Secrets;
  • SandboxUpdateOps with CheckpointRestore and paused-instance upgrades — upgrade a hibernated fleet without waking it by hand, and upgrade without losing the root filesystem;
  • PoolAutoscaler — declarative warm pool capacity, with watermarks and cron schedules;
  • Automatic pause and resume — probe-driven idle detection, scheduled wake, and wake-on-traffic, so an idle Sandbox stops consuming CPU without any manual intervention.

Read together, these are three kinds of customer value: security hardening (an Agent that runs untrusted code can no longer reach whatever it wants, and never holds your API keys), operational capability (batch upgrades, autoscaling, and lifecycle automation become declarative instead of scripted), and cost optimization (idle Sandboxes hibernate, warm pools shrink at night, and paused fleets still receive upgrades).

This post is organized in three parts: the architecture changes that made all of this possible, a deep dive into the four features, and the value and roadmap summary.


Part One: What Changed in the Architecture​

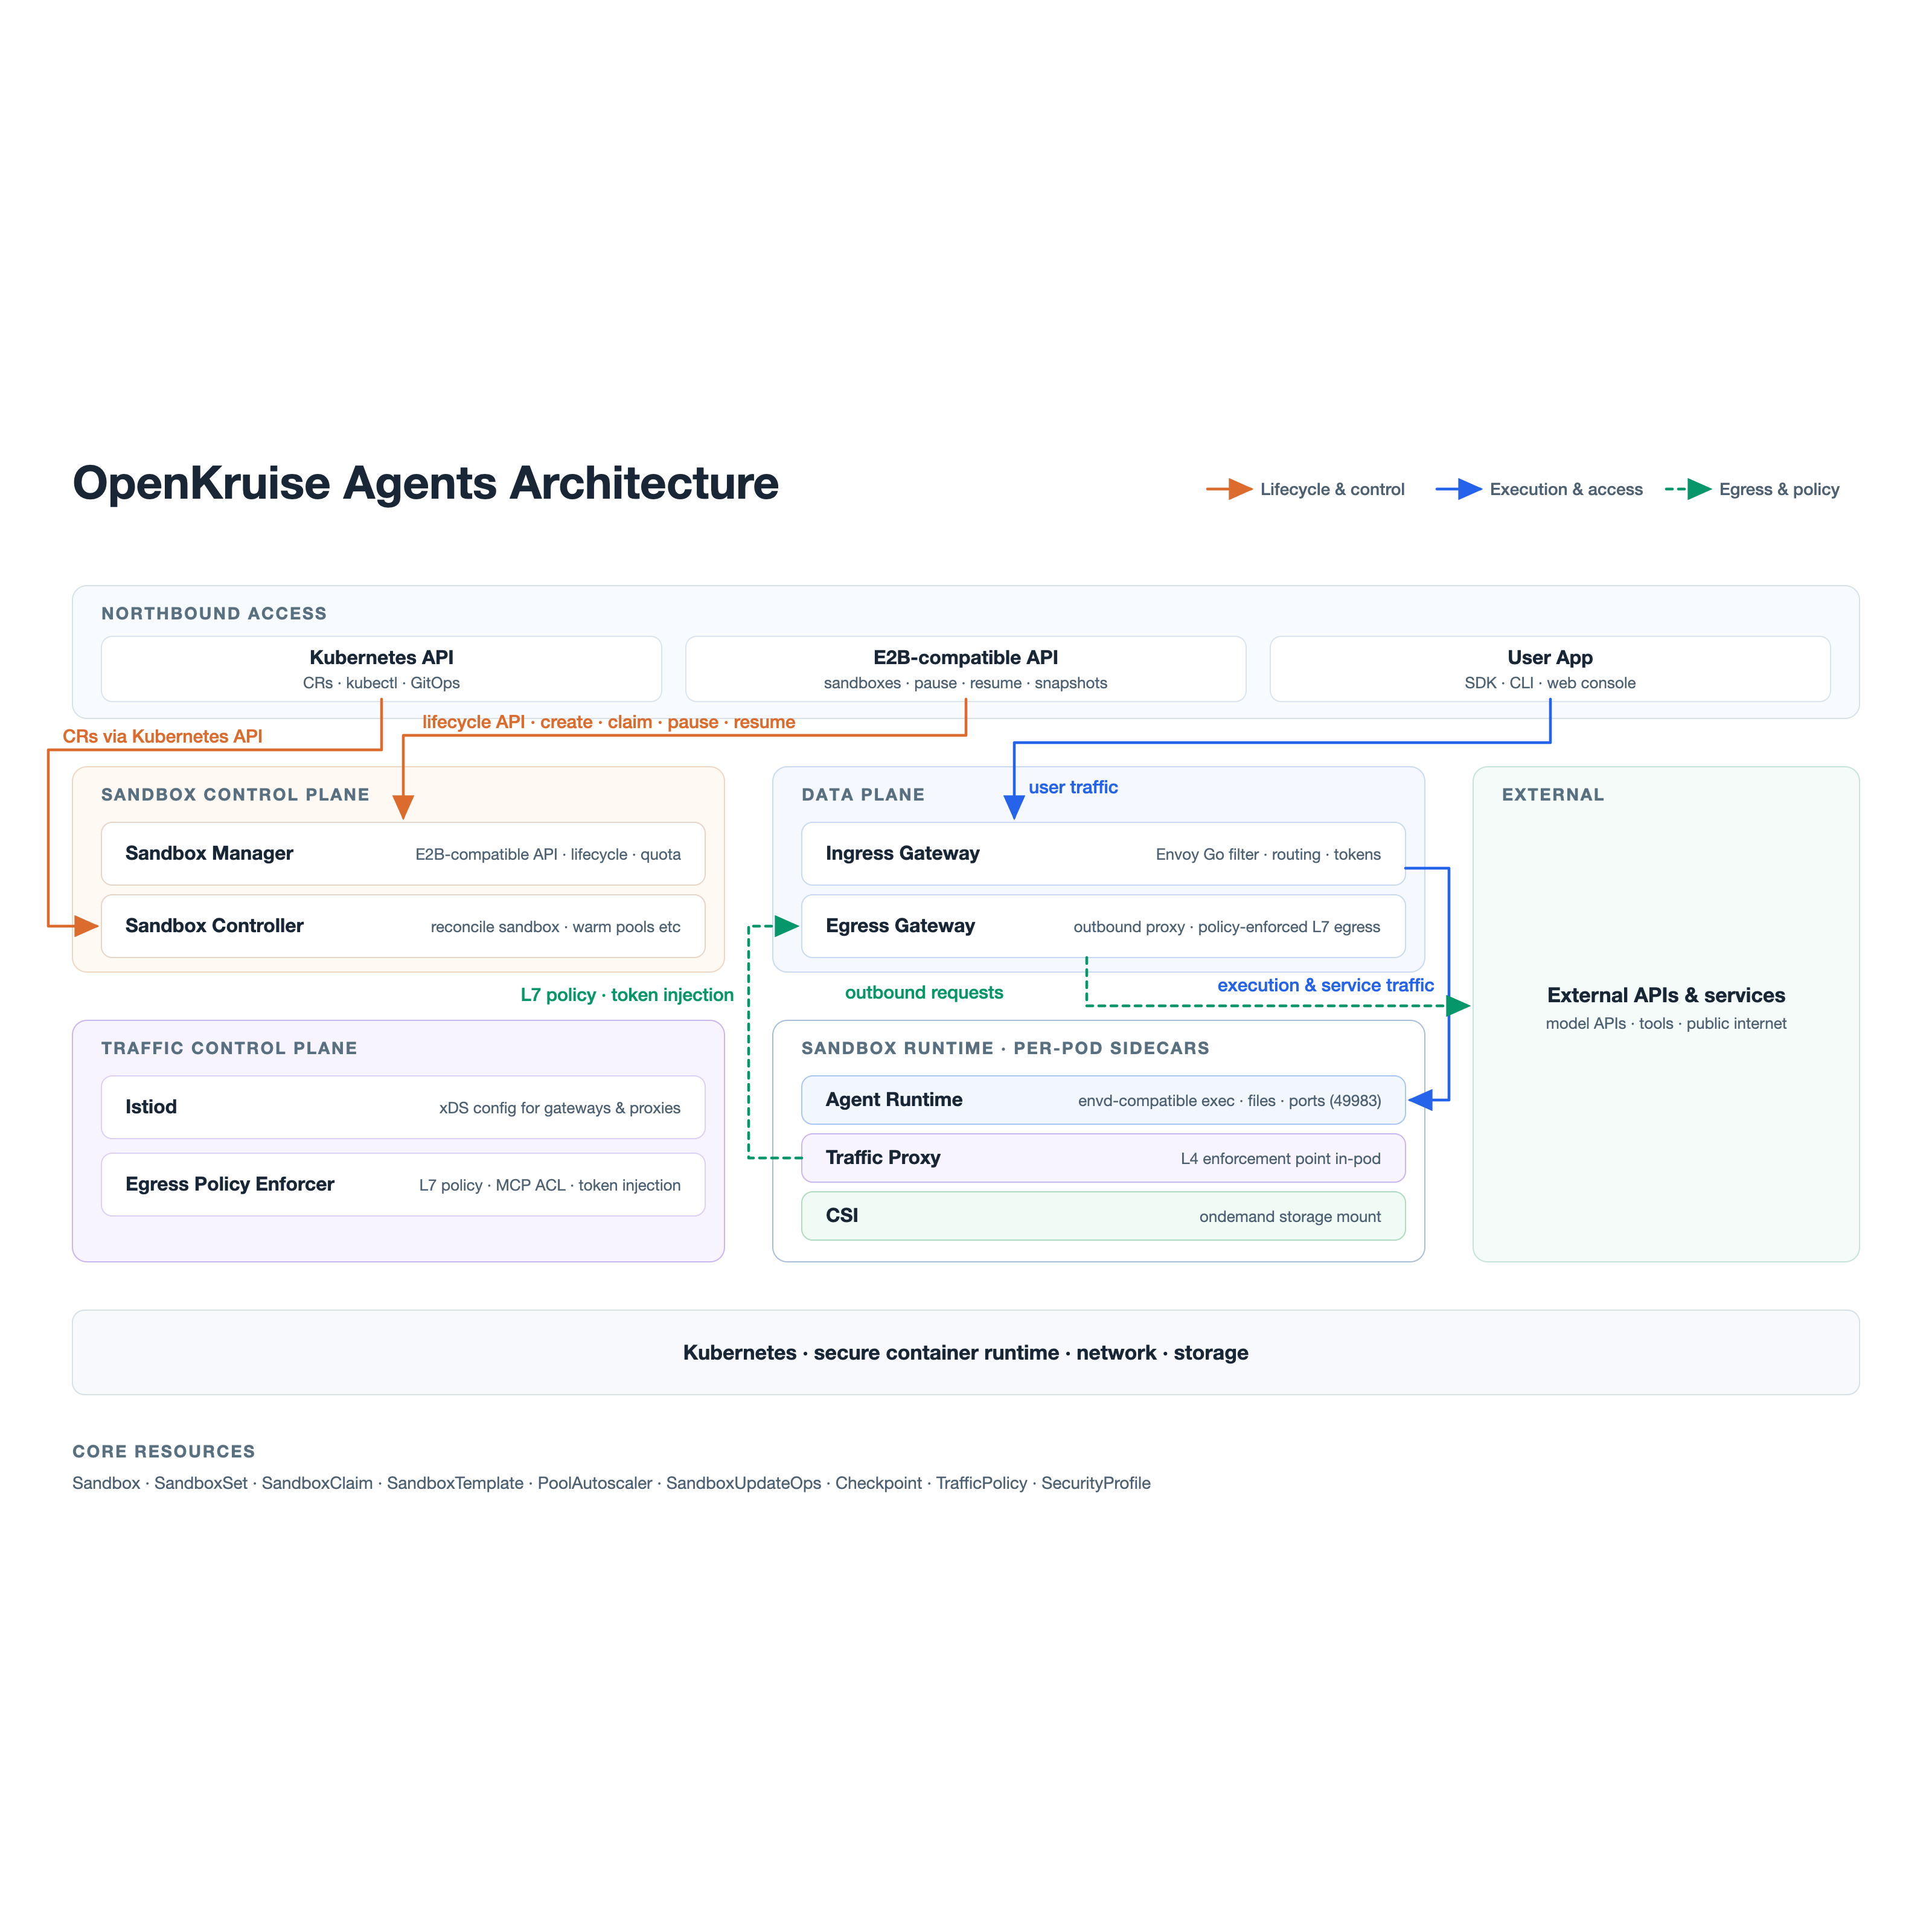
If v0.3.0 was a workload layer, v0.6.0 is a workload layer with its own data plane. The full component model is documented in Architecture; the short version is that traffic inspection, policy distribution, and identity all became first-class components rather than external addons.
alt

1.1 From Four Components to Six​

ComponentRole in v0.6.0
sandbox-managerStateless backend that serves the E2B-compatible northbound API and owns sandbox lifecycle, quota, and route & traffic-token orchestration
sandbox-controllerReconciles Sandbox, SandboxSet, SandboxClaim and warm pools, and hosts the admission webhooks. In v0.6.0 it also drives the automatic pause/resume controller
sandbox-gatewayThe data plane, built as Envoy Go filters. The ingress gateway proxies user traffic to sandboxes with host/path routing, access tokens, and wake-on-traffic. The egress gateway proxies outbound sandbox traffic with policy-enforced L7 egress
traffic-control-planeNew. istiod distributes xDS configuration to the gateways and the in-pod proxies; the Egress Policy Enforcer (EPE) applies L7 policy, MCP ACL, and token injection on egress traffic
agent-runtimeSidecar providing E2B envd-compatible command, file, and port (49983) operations
traffic-proxyNew. A sidecar that acts as the in-pod L4 enforcement point for egress traffic policies

Two consequences are worth internalizing. First, egress is no longer the Pod's own business — it is captured in-pod, routed through an egress gateway, and decided by a policy engine that sees the request, not just the socket. Second, the ingress gateway can wake a sandbox, which is what makes wake-on-traffic possible without an external poller.

1.2 The Enforcement Path​

Every gateway-routed outbound request from a Sandbox running the traffic-proxy runtime walks the same path:

Sandbox application container
-> TrafficProxy in-pod capture
-> egress gateway chosen by egress routing
-> Envoy external processing
-> Egress Policy Enforcer decision
-> external service, or a blocked response

The split of responsibility is deliberate: EPE compiles TrafficPolicy / GlobalTrafficPolicy and pushes them to the data plane, so an L4 rejection is dropped before the gateway. EPE only inspects L7 for gateway-routed HTTP requests — direct passthrough traffic never reaches it, and L7 cannot override an L4 rejection.

1.4 The CRD Surface Doubled​

v0.3.0 shipped six CRDs. v0.6.0 ships twelve:

CRDScopeRole
SandboxNamespacedA single sandbox instance with full lifecycle operations
SandboxSetNamespacedManages a batch of homogeneous Sandboxes; maintains the warm pool
SandboxTemplateNamespacedImmutable template version snapshot for version tracing
SandboxClaimNamespacedClaims an idle Sandbox and performs post-processing (image swap, mounts, in-place resize)
CheckpointNamespacedRuntime snapshot (memory and/or rootfs) used to fork new instances
CommitNamespacedAlpha, behind the Commit feature gate. Saves the writable layer as a new image and pushes it to a registry
SandboxUpdateOpsNamespacedOne-shot batch upgrade of claimed Sandboxes
PoolAutoscalerNamespacedNew. Declarative warm pool capacity and cron scaling
TrafficPolicyNamespacedNew. L3/L4 egress and ingress destination control
GlobalTrafficPolicyClusterNew. Cluster-scoped L4 baseline
SecurityProfileNamespacedNew. L7 request inspection, MCP ACL, credential injection, audit
GlobalSecurityProfileClusterNew. Cluster-scoped L7 baseline

1.5 E2B Compatibility Moved Forward, With Documented Edges​

The northbound API stays E2B-compatible, and the compatibility matrix is now explicit about where it is partial:

  • pause is fully compatible and synchronous — the request blocks until the Sandbox reaches Paused;
  • create is partially compatible — network access control is supported, MCP integration on the create path is still pending;
  • network is partially compatible — allowOut, denyOut, and rules are supported; egressProxy and maskRequestHost are rejected outright rather than silently ignored;
  • Not yet supported: pre-signed upload/download URLs, logs, metrics, lifecycle events, and Volumes.

Part Two: The Four Features in Depth​

2.1 Network Access Control and Token Management​

This is the largest single area of the release, and it answers three distinct questions: what may a Sandbox reach, who is allowed to reach the Sandbox, and — the one most platforms get wrong — who holds the upstream API key.

Layer 4: Is the Destination Reachable at All​

TrafficPolicy selects calling Pods and holds an ordered egress rule list. Every rule must declare to, and may declare action (allow or reject) and a ports list. A peer accepts fqdn, cidr, service, or workload, and multiple peers are ORed.

apiVersion: agents.kruise.io/v1alpha1
kind: TrafficPolicy
metadata:
name: sandbox-egress
namespace: default
spec:
selector:
matchLabels:
app: traffic-sample
egress:
rules:
- action: allow
to:
- service:
name: kube-dns
namespace: kube-system
- action: allow
to:
- fqdn: api.example.com
- action: reject
ports:
- protocol: TCP
port: 443
to:
- cidr: 10.0.0.0/8

Three semantics matter more than the syntax:

  • Once a policy selects a Pod, outbound traffic matching no allow rule is rejected. The policy is an allowlist the moment it attaches;
  • A rule missing its peer field is skipped by the compiler — it does not establish a default deny. A typo in to weakens your policy silently;
  • Always allow the cluster DNS Service, or hostname resolution fails and every FQDN rule looks broken.

GlobalTrafficPolicy is the cluster-scoped equivalent, for baselines your platform team owns centrally.

Layer 7: What May This Specific Request Do​

SecurityProfile matches HTTP requests and applies actions. Each rule has a unique name, at least one match clause, and actions. Clauses in match are ORed; every populated field inside one clause is ANDed; domains is required.

The action set is small and its terminal behavior is the part to memorize:

ActionTerminalBehavior
blockYesReturns statusCode (default 403) with an optional body, never forwards upstream, discards pending mutations
bypassYesForwards the request and skips every remaining action and rule, preserving mutations already applied
mcpToolPolicyNoAllows or denies MCP JSON-RPC tools/call requests by tool name
headerManipulationNoSets or removes plaintext headers. Values are stored verbatim — never use it for credentials
tokenTransformationNoRewrites a request credential from a Secret or credential provider. Governed by failStrategy, default Block
auditNoSends an asynchronous webhook event; never changes the decision

Evaluation order is a merge, not a namespace-local list: lower spec.priority first (default 1000), then earlier creation time, name, and namespace. Global and namespaced profiles share this order, and an exact tie places the global profile first. Matching is not first-rule-wins — a later rule can still match after a broad earlier rule; only a terminal action stops the chain. Within one rule, actions run in the fixed order bypass, block, mcpToolPolicy, headerManipulation, tokenTransformation, regardless of YAML key order.

A representative baseline that blocks management paths anywhere:

apiVersion: agents.kruise.io/v1alpha1
kind: SecurityProfile
metadata:
name: deny-management-paths
namespace: default
spec:
selector:
matchLabels:
app: traffic-sample
rules:
- name: deny-management-paths
match:
- domains:
- "*"
paths:
- type: Prefix
value: /admin
- type: Prefix
value: /console
- type: Prefix
value: /dashboard
actions:
block:
statusCode: 403
body: '{"error":"management paths are blocked"}'

The highest-value profile for Agent workloads, though, is the SSRF guard. Prompt-injected code reliably tries to reach internal services and cloud metadata endpoints:

apiVersion: agents.kruise.io/v1alpha1
kind: GlobalSecurityProfile
metadata:
name: cluster-baseline
spec:
selector:
matchLabels:
app: traffic-sample
priority: 50
rules:
- name: deny-metadata-endpoint
match:
- domains:
- metadata.internal
- "*.internal.company.com"
- "*.corp.net"
actions:
block:
statusCode: 403
body: '{"error":"access to internal services is forbidden"}'

Note priority: 50 — a cluster baseline should sort ahead of tenant profiles on purpose, and a GlobalSecurityProfile must not set metadata.namespace.

MCP Tool-Level ACL​

When an Agent talks to an MCP server, domain-level control is too coarse: the dangerous operation is a specific tool. mcpToolPolicy governs only JSON-RPC tools/call and matches the exact params.name; tools/list and initialize pass through.

apiVersion: agents.kruise.io/v1alpha1
kind: SecurityProfile
metadata:
name: mcp-tool-whitelist
namespace: default
spec:
selector:
matchLabels:
app: traffic-sample
rules:
- name: protect-mcp-tools
match:
- domains:
- mcp.example.com
schemes:
- https
paths:
- type: Prefix
value: /mcp
actions:
mcpToolPolicy:
defaultAction: deny
unsupportedVersionAction: deny
denyResponse:
statusCode: 403
body: MCP tool is not permitted
rules:
- method: tools/call
toolNames:
- read_file
- search_docs
action: allow

Rules are evaluated in document order and the first match wins; an empty toolNames list matches every tool for that method. Use defaultAction: deny for a whitelist — with defaultAction: allow, an unreadable body or an unnameable tool call is allowed by design. The enforcer buffers the full body, so payloads over 8 MiB, JSON-RPC batches, and unsupported encodings fall back to defaultAction. Supported MCP protocol versions are 2025-06-18, 2025-11-25, and 2026-07-28.

Credential Injection: Your API Key Never Enters the Sandbox​

This is the piece that changes the security conversation with your compliance team. The credential lives in a Kubernetes Secret; the egress proxy resolves it per request and rewrites the outbound request just before it leaves the cluster. The workload and the Agent code only ever see their own placeholder header.

apiVersion: v1
kind: Secret
metadata:
name: example-api-credentials
namespace: agent-demo
type: Opaque
stringData:
apiKey: REPLACE_WITH_YOUR_API_KEY
apiVersion: agents.kruise.io/v1alpha1
kind: SecurityProfile
metadata:
name: example-api-credentials
namespace: agent-demo
spec:
selector:
matchLabels:
app: agent
rules:
- name: inject-example-api-key
match:
- domains:
- api.example.com
schemes:
- https
paths:
- type: Prefix
value: /v1/
actions:
tokenTransformation:
type: ApiKey
failStrategy: Block
credentialRef:
secret:
name: example-api-credentials
apiKey:
targetHeaders:
names:
- authorization
value:
template: "Bearer {{ .Token }}"

Because resolution happens at the proxy, the credential is not in the Pod spec, the environment, or Sandbox metadata — and rotating the Secret takes effect without restarting the Sandbox. credentialRef.secret.namespace is optional: a SecurityProfile falls back to its own namespace, a GlobalSecurityProfile to each selected Pod's namespace. Exactly one of secret or credentialProvider may be set, targetHeaders.cel supports dynamic header names, and failStrategy defaults to Block so a missing credential fails closed rather than leaking an unauthenticated call.

E2B-Native Network Controls​

Teams that do not want to write CRDs can express network intent through the E2B SDK, provided the Sandbox runs traffic-proxy:

from e2b_code_interpreter import Sandbox

sandbox = Sandbox.create(
template="code-interpreter",
network={
"allow_out": ["api.example.com", "10.0.0.0/8"],
"deny_out": ["0.0.0.0/0"],
},
)

The asymmetry to remember: allowOut accepts IPs, CIDRs, and concrete FQDNs (wildcards rejected), while denyOut accepts IPs and CIDRs only. Hostname filtering is therefore expressed as an allowlist plus a 0.0.0.0/0 deny, and allow beats deny. rules carries per-domain header transforms and does not grant reachability. Updates go through PUT /sandboxes/{sandboxID}/network or sandbox.update_network(...): an omitted rules key keeps the existing chain, an empty object clears it, a non-empty one replaces it.

These controls compose into a hierarchy: cluster-scoped GlobalTrafficPolicy and GlobalSecurityProfile set the global baseline, namespace-scoped TrafficPolicy and SecurityProfile carry per-tenant rules, and per-Sandbox inline network controls apply to a single Sandbox — multi-layered, fine-grained network access control from the global dimension down to the tenant and the individual Sandbox.

Guardrails You Should Not Skip​

The four manuals behind this section are Traffic Access Control, E2B Network Controls, Credential Injection, and Traffic Access Token Rotation. They are explicit about the limits, and so is this post:

  • Enforcement covers gateway-routed traffic only. HTTPS inspection additionally requires TLS termination, a signing CA, and workload trust;
  • A container running as root or with NET_ADMIN / SYS_ADMIN can bypass the in-pod ACLs. Pair these policies with Kubernetes NetworkPolicies, a host firewall, or cloud security groups — this is defense in depth, not a single wall;
  • TrafficProxy reserves ports 15001, 15006, 15012, 15020, 15021, 15090 and runs as UID/GID 1337;
  • A forged Host header can evade L4 matching, which is exactly why L7 profiles exist;
  • Per-Sandbox inline rules (agents.kruise.io/security-rules) are evaluated after selector-matched profiles; a compile failure keeps the previous rules or enforces none, surfaced by the epe_profile_stale and epe_profile_unenforced metrics with scope="pod";
  • EPE is a network hop on every gateway-routed request. Size its Deployment independently of the gateways.

2.2 SandboxUpdateOps: CheckpointRestore and Upgrading Paused Sandboxes​

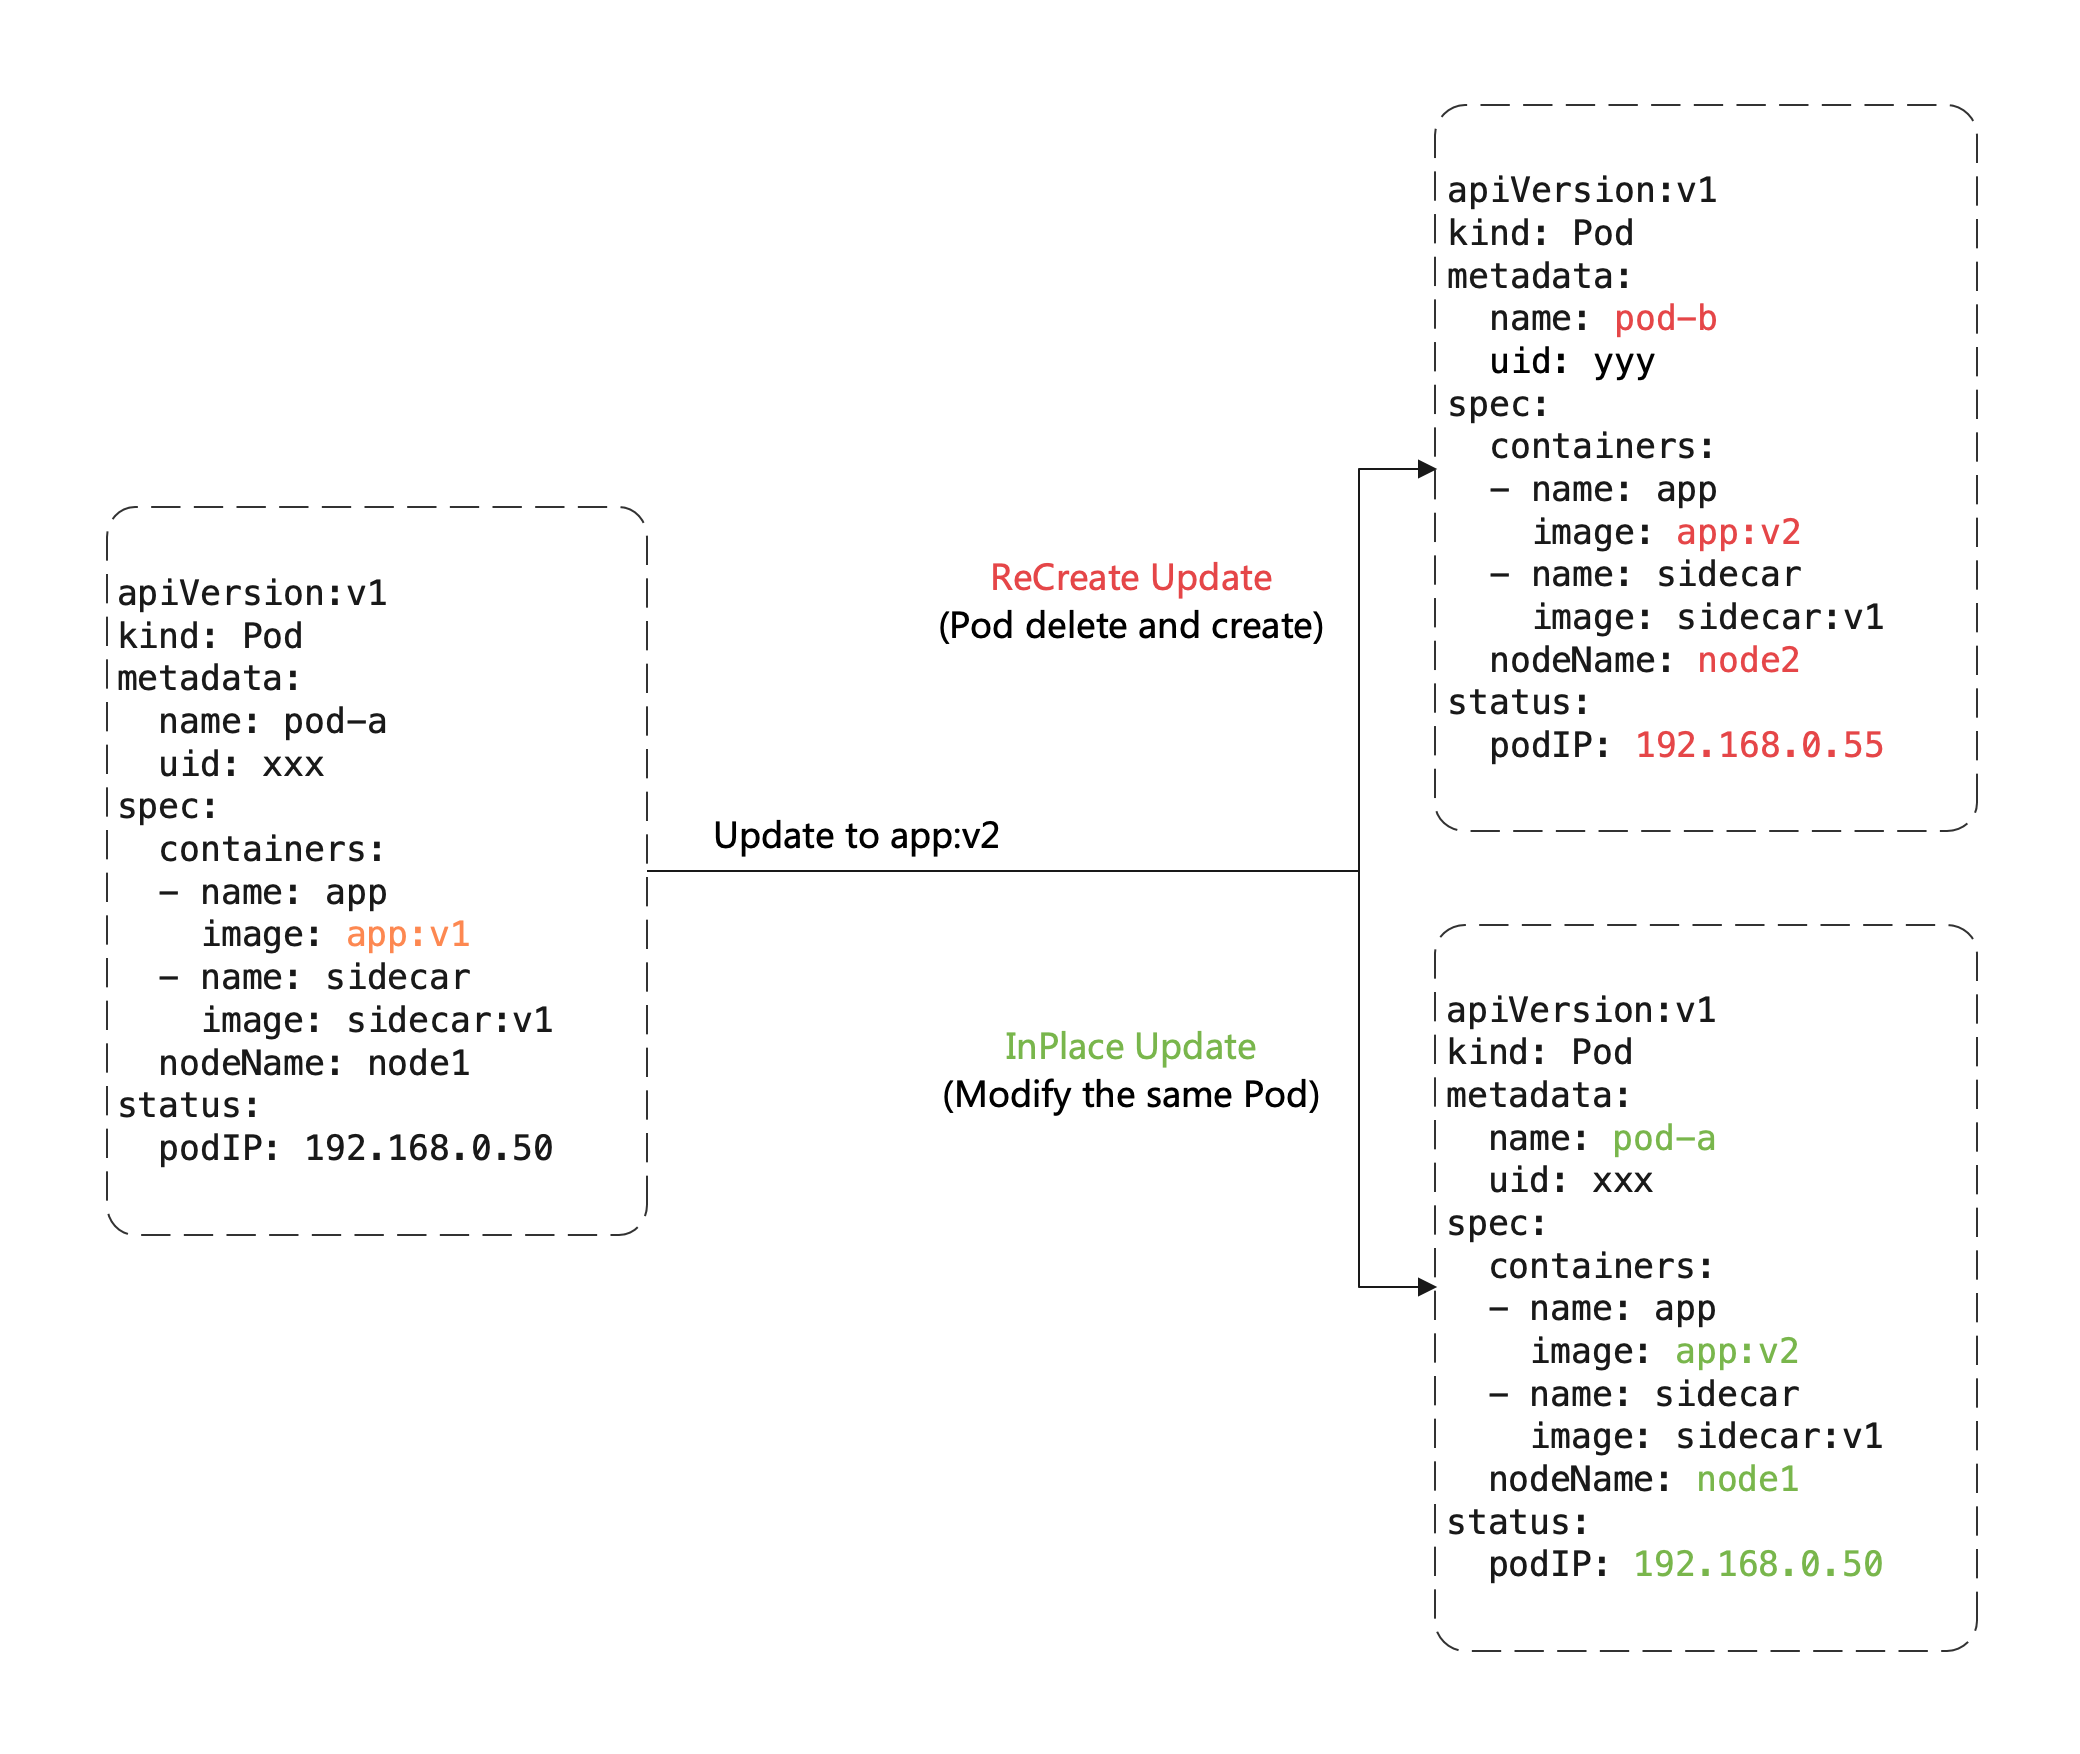
v0.3.0 introduced SandboxUpdateOps with a single mode: Recreate, meaning the Pod is destroyed and rebuilt, so memory, IP, and the rootfs writable layer are all lost, and preUpgrade / postUpgrade hooks are your only way to carry state across. v0.6.0 adds two things users asked for immediately: a mode that preserves the rootfs, and the ability to include paused Sandboxes in a batch upgrade. Both require v0.6.0; the base flow works from v0.3.0. Details are in Sandbox Update.
alt

Two Upgrade Modes​

ModeRootfsMemoryIPBusiness image change
Recreate (default)LostLostChangedSupported
CheckpointRestorePreserved — checkpointed before, restored afterLostChangedNot supported

CheckpointRestore trades image flexibility for data continuity. The constraint is absolute: you cannot change the business container image under CheckpointRestore — doing so discards the restored rootfs, which is the entire point of the mode. What you can do is roll sidecar versions and any non-image field:

apiVersion: agents.kruise.io/v1alpha1
kind: SandboxUpdateOps
metadata:
name: upgrade-sidecar
namespace: default
spec:
updateStrategy:
type: CheckpointRestore
patch:
metadata:
annotations:
agents.kruise.io/upgrade-sidecar: "20260714"

That is the pattern for a fleet-wide agent-runtime or traffic-proxy bump: no user data touched, no backup scripts to write, no restore window to schedule. For an image change with state, Recreate plus hooks remains the answer — back up to OSS or NAS in preUpgrade, restore in postUpgrade.

Upgrading Hibernated Sandboxes​

Before v0.6.0, SandboxUpdateOps only touched Sandboxes in Running or Upgrading phase. A paused fleet was invisible to it, which forced operators into an awkward manual cycle of wake, upgrade, re-pause — and made a hibernated pool a standing source of version drift.

stateFilter fixes this:

apiVersion: agents.kruise.io/v1alpha1
kind: SandboxUpdateOps
metadata:
name: upgrade-with-paused
namespace: default
spec:
stateFilter:
states:
- Running
- Paused
selector:
matchLabels:
agents.kruise.io/sandbox-template: my-sandbox-pool
updateStrategy:
maxUnavailable: 10%
patch:
spec:
containers:
- name: sandbox
image: my-registry/sandbox-image:v2

The controller wakes each paused Sandbox, upgrades it, then re-pauses it if spec.paused is still true. The end state of the fleet is the same shape as the start state — paused Sandboxes stay paused — so an upgrade does not silently convert a hibernated pool into a billing event.

2.3 PoolAutoscaler: Warm Pool Capacity as a Policy​

Warm pools are the reason OpenKruise Agents delivers sub-second claims, and they are also the reason a platform team's bill grows on Saturday night when nobody is using it. PoolAutoscaler turns pool sizing into a declarative policy instead of a cron job that runs kubectl scale.

Be precise about what it does: PoolAutoscaler rewrites SandboxSet.spec.replicas. It does not collect business metrics, predict traffic, or create and delete Pods itself — the SandboxSet controller does that. What it gives you is watermark-driven feedback on available capacity, plus time-driven overrides.

Capacity Policy​

apiVersion: agents.kruise.io/v1alpha1
kind: PoolAutoscaler
metadata:
name: sandbox-pool-scaler
namespace: default
spec:
scaleTargetRef:
kind: SandboxSet
name: sandbox-pool
minReplicas: 2
maxReplicas: 50
capacityPolicy:
targetAvailable: "50%"
tolerance: "10%"
scaleUp:
stabilizationWindowSeconds: 60
scaleDown:
stabilizationWindowSeconds: 300

targetAvailable: "50%" means the scaler keeps available Sandboxes at half of total replicas — a buffer that absorbs a claim burst while the pool refills. Watermarks are computed as ceil(avgReplicas x (target +/- tolerance)%), with tolerance defaulting to 10%. Asymmetric stabilization windows (fast up, slow down) are the right default for a warm pool: users feel a shortage immediately and never notice a gradual shrink.

Cron Policies​

For known traffic shapes, cron wins — it triggers ahead of the burst rather than reacting to it:

apiVersion: agents.kruise.io/v1alpha1
kind: PoolAutoscaler
metadata:
name: sandbox-pool-scaler
namespace: default
spec:
scaleTargetRef:
kind: SandboxSet
name: sandbox-pool
minReplicas: 2
maxReplicas: 50
cronPolicies:
- name: weekday-peak
timezone: Asia/Shanghai
schedule: "30 8 * * 1-5"
targetReplicas: 30
- name: weekday-offpeak
timezone: Asia/Shanghai
schedule: "0 20 * * 1-5"
targetReplicas: 5

Cron takes priority when triggered and is not subject to the capacity stabilization windows, but it is still clamped by minReplicas / maxReplicas. Set timezone explicitly — the schedule is five-field cron, and validation allows up to 20 entries with unique names.

Tuning Traps​

  • Do not set targetAvailable: "100%" — the pool then only ever grows;
  • Scale-down reachability has hard arithmetic. For absolute values, target + downTolerance must not exceed minReplicas; for percentages, p + q must not exceed 100 x minReplicas / (minReplicas + 1). Otherwise the policy can never trigger a shrink and validation is your only warning;
  • tolerance must be strictly less than targetAvailable; a percentage target requires minReplicas of at least 1; stabilization windows are 60 to 3600 seconds;
  • Validation failures return HTTP 422, including a scaleTargetRef.kind that is not SandboxSet, maxReplicas at or below 0, or minReplicas above maxReplicas;
  • spec.suspend: true pauses the scaler without deleting it — the right move during an incident;
  • Deleting a PoolAutoscaler leaves spec.replicas at its last value. The pool does not shrink back on its own.

2.4 Automatic Pause and Resume​

A claimed Sandbox with an active user session and a claimed Sandbox where nobody has typed in four hours look identical to Kubernetes. Automatic pause and resume makes the difference observable, and acts on it.

The feature is configured on SandboxSet through two top-level spec fields — probes and autoPausePolicy — and probe-driven pause plus scheduled wake require the AutoPauseController feature gate on sandbox-controller, which is enabled by default. Probes on real nodes additionally require OpenKruise installed (for kruise-daemon) and the KruiseIntegration feature gate — otherwise real-node probe conditions stay Unknown and automatic pause never triggers; probes on virtual-kubelet nodes are unaffected. Inbound-traffic wake applies only to gateway-routed requests to claimed Sandboxes, and needs the gateway flags enable-wake-on-traffic and wake-timeout-seconds (default 60, after which the caller gets 503 sandbox wake failed). Both are gateway-level.

Probes: Exec Only, Message-Driven​

apiVersion: agents.kruise.io/v1alpha1
kind: SandboxSet
metadata:
name: openclaw-sbs
namespace: default
spec:
probes:
- name: Active
periodSeconds: 30
timeoutSeconds: 5
exec:
command:
- sh
- -c
- |
if openclaw sessions list --active 900 | grep -q .; then
printf 'active'
else
printf 'inactive'
fi

Each probe needs a unique name (it becomes condition type agents.kruise.io/<name>), an optional containerName (defaults to the first container), and only exec is supported — no HTTP, no TCP. The command is not shell-wrapped, so write sh -c yourself. Exit code 0 produces status: "True" with stdout in message; a failed or timed-out probe never triggers a pause or a wake, which is the safe direction.

Idle-Driven Pause​

  autoPausePolicy:
probe: Active
pause:
whenProbedIdleState:
probe: Active
messageRegex: "^inactive$"
thresholdDuration: 10m

thresholdDuration is required and non-negative; 0 means pause on the first idle report. The window arithmetic is worth spelling out for capacity planning: with a 30-second period, a 15-minute inactivity window inside the probe command, and a 10-minute threshold, the Sandbox pauses roughly 25 minutes after the last real activity. The pending pause is visible in status.schedules as reason: probedIdle with a nextPauseTime, and a later active reading clears it.

Warm unclaimed Sandboxes run the probes but do not participate in pause decisions — the pool is managed by PoolAutoscaler, not by auto-pause.

Scheduled Wake​

Some workloads are idle on a schedule: a notebook that only matters at 9am, an RL rollout that runs nightly. A second probe can print the next activation time, and the controller wakes the Sandbox ahead of it:

  autoPausePolicy:
resume:
whenProbedScheduleTime:
probe: Cron
timeFormat: unix
leadTime: 5m

timeFormat is unix (default, positive integer seconds) or datetime (RFC 3339 with timezone). leadTime defaults to 5m, may be 0, and may not be negative; wake happens at task time minus lead time, surfaced as reason: probedSchedule with nextResumeTime. Two classic bugs: printing milliseconds from the probe (divide by 1000), and converting local business time to a timestamp inside the probe instead of emitting a timezone-aware value.

Wake on Inbound Traffic​

This is the path that makes pausing safe for user-facing Sandboxes — the first request after a pause wakes the Sandbox instead of failing:

from e2b_code_interpreter import Sandbox

sandbox = Sandbox.create(
template="code-interpreter",
timeout=600,
lifecycle={
"on_timeout": "pause",
"auto_resume": True,
},
)
host = sandbox.get_host(3000)

After a wake, the timeout countdown restarts from the wake-up moment using the creation timeout, and positive values below 5 minutes are treated as 5 minutes. sandbox.commands.run(...) and sandbox.files.write(...) also trigger a wake. In CRD form the same re-arm is autoPausePolicy.resume.onIngressTraffic.pauseTimeout: 5m, which applies only to Sandboxes that have spec.pauseTime set — if it is unset or not greater than 0, the countdown is not reset. On its own onIngressTraffic pauses nothing; it only governs the resume behavior.

Three behaviors are universal and will otherwise cost you an afternoon:

  • The request must be authorized. An unauthorized request gets 401 and the Sandbox stays paused — wake-on-traffic is not an unauthenticated doorbell;
  • A successful wake can accompany a failed request. The triggering call may return 503 upstream connect error, or 503 sandbox wake failed if it arrives mid-transition to paused. Check Sandbox.status.phase and retry;
  • A warm Sandbox is still owned by its SandboxSet, so a request to one returns 502 healthy sandbox not found.

Part Three: Customer Value, Roadmap, and Community​

3.1 What This Buys You​

Before v0.6.0With v0.6.0
Security hardeningEgress was the Pod's own business; a prompt-injected Sandbox could reach internal services, cloud metadata, and any MCP tool the server exposed. Upstream API keys had to be handed to the Agent runtime. Long-lived opaque tokens bounded replay exposure to "forever"L3/L4 allowlists with TrafficPolicy, L7 request inspection with SecurityProfile, MCP tool whitelists, a cluster-wide Global* baseline layer, credentials resolved at the egress proxy from a Secret and rotatable without restart, and short-lived rotating JWT traffic access tokens
Operations capabilityPaused Sandboxes were invisible to batch upgrades, so hibernated fleets drifted. Pool sizing was a cron job calling kubectl scale. Idle detection was somebody's shell scriptSandboxUpdateOps covers Running and Paused via stateFilter and preserves the rootfs via CheckpointRestore; PoolAutoscaler makes capacity declarative with watermarks and cron; auto pause/resume turns idle detection into a probe
Cost optimizationA claimed Sandbox burned CPU whether or not anyone was using it, and the warm pool was sized for peak around the clockIdle Sandboxes hibernate on probe evidence and wake on schedule or on first request; pools shrink at 20:00 and grow at 08:30; CheckpointRestore upgrades and paused-fleet upgrades avoid both data loss and unnecessary wake cycles

3.2 What Is Next: Community Capability Building​

The roadmap ahead emphasizes community capability building — building with other open-source communities instead of growing a proprietary stack:

  • Open-source checkpoint with the Kata Containers community — implement an open-source checkpoint capability on top of the PodCheckpoint API introduced in Kubernetes 1.37, in collaboration with the Kata community, moving beyond today's platform-specific snapshot backend;
  • On-demand mounting for open-source storage — build on the existing on-demand volume mounting framework so open-source storage solutions such as MinIO can be mounted into a Sandbox on demand;
  • Integration with open-source identity systems — such as Keycloak, so platform authentication can be unified with your existing identity provider.

3.3 Community​

OpenKruise Agents is built in the open, and this release had 27 new contributors. If you are running Agent sandboxes on Kubernetes, the fastest way to shape the roadmap is to file an issue or join the community call.

OpenKruise Agents v0.6.0 is now available on GitHub Releases and major container registries. We look forward to your feedback and Pull Requests.

OpenKruise V1.9 Release, API v1beta1, Cron Imagepulling, and More

· 9 min read
Zhen Zhang
Maintainer of OpenKruise

OpenKruise (https://github.com/openkruise/kruise) is an open-source cloud-native application automation management suite. It is also a current incubating project hosted by the Cloud Native Computing Foundation (CNCF). It is a standard extension component based on Kubernetes that is widely used in production of internet scale company. It also closely follows upstream community standards and adapts to the technical improvement and best practices for internet-scale scenarios.

OpenKruise has released the latest version v1.9.0 on June 21, 2026 (ChangeLog). This release brings API upgrades to v1beta1, Windows node support, and several new features. This article introduces the key features in detail and briefly covers other notable changes.

Upgrade Notice​

  • Kubernetes dependency has been updated to v1.32.6 and Golang to v1.23. Make sure your cluster is compatible.
  • API v1alpha1 → v1beta1: BroadcastJob, AdvancedCronJob, ImagePullJob, ImageListPullJob, NodeImage, Advanced DaemonSet, and SidecarSet APIs have been upgraded from v1alpha1 to v1beta1. The v1alpha1 APIs are still supported but deprecated, and conversion webhooks handle automatic migration transparently. Users are strongly encouraged to update their manifests to v1beta1 before upgrading to OpenKruise v2.0.

In addition to the apiVersion change, several fields were updated during the promotion:

SidecarSet field changes:

  • spec.namespace is deprecated — use spec.namespaceSelector with the kubernetes.io/metadata.name label instead.
  • The "apps.kruise.io/sidecarset-custom-version" annotation is replaced by the spec.customVersion field.
# Before (v1alpha1)
apiVersion: apps.kruise.io/v1alpha1
kind: SidecarSet
metadata:
annotations:
apps.kruise.io/sidecarset-custom-version: "v1"
spec:
namespace: default
# After (v1beta1)
apiVersion: apps.kruise.io/v1beta1
kind: SidecarSet
metadata:
name: my-sidecarset
spec:
customVersion: v1
namespaceSelector:
matchLabels:
kubernetes.io/metadata.name: default

Advanced DaemonSet field changes:

  • The "daemonset.kruise.io/progressive-create-pod" annotation is replaced by spec.scaleStrategy.
  • status.DaemonSetHash is replaced by status.UpdateRevision.
  • spec.partition type changed from *int32 to *intstr.IntOrString — now supports percentage values like 50%.
  • spec.updateStrategy.rollingUpdate.type: Surging is deprecated — use Standard instead.
# After (v1beta1) — partition now supports percentage
apiVersion: apps.kruise.io/v1beta1
kind: AdvancedDaemonSet
spec:
partition: "50%"
updateStrategy:
rollingUpdate:
type: Standard

For the full list of API promotions and field changes, see the API Upgrade Guide.

Note: The v1alpha1 API for Advanced StatefulSet will be removed in OpenKruise v2.0. Other v1alpha1 APIs have no removal plan yet, but migration is recommended to avoid conversion webhook overhead.

Key Features​

UnitedDeployment ReserveUnschedulablePods​

In elastic scenarios, you often want to prioritize scheduling Pods on owned node pools (e.g., self-built IDC) and use elastic node pools (e.g., virtual-kubelet) as fallback. The existing Adaptive strategy permanently moves Pods to other subsets when the target subset is unschedulable. However, this means you lose the preferred topology — even after the original subset recovers, the Pods stay where they were moved.

v1.9.0 introduces reserveUnschedulablePods under the Adaptive scheduling strategy. When enabled, unschedulable Pods are reserved in the target subset, and a temporary replica is created in the next available subset to maintain the expected replica count. Once the target subset becomes schedulable again, the temporary replica is deleted and the reserved Pod is scheduled back to the original subset.

apiVersion: apps.kruise.io/v1alpha1
kind: UnitedDeployment
metadata:
name: sample-ud
spec:
topology:
scheduleStrategy:
type: Adaptive
adaptive:
reserveUnschedulablePods: true
rescheduleCriticalSeconds: 30
subsets:
- name: ecs
nodeSelectorTerm:
matchExpressions:
- key: node-type
operator: In
values: [ecs]
- name: vk
nodeSelectorTerm:
matchExpressions:
- key: node-type
operator: In
values: [virtual-kubelet]

In this example, Pods are prioritized on ECS nodes. When ECS nodes are full, temporary replicas are created on virtual-kubelet nodes. Once ECS capacity is restored (e.g., after node scaling), the temporary replicas are removed and Pods migrate back to ECS.

Limitation: Only works with the Adaptive scheduling strategy. The temporary replica creation is recursive across subsets.

AdvancedCronJob Cron ImagePullJob​

For AI/ML workloads that use large images (e.g., several GB), pre-pulling images before Pod scheduling significantly reduces startup time. In large model workload clusters, nodes frequently garbage-collect (GC) images due to disk space pressure, so pre-warming needs to be re-run before scheduled tasks to ensure effectiveness. Previously, you had to manually create ImagePullJob resources or use external cron tools. Now you can schedule image pre-pulling as a cron task directly within AdvancedCronJob using the new imageListPullJobTemplate field.

apiVersion: apps.kruise.io/v1beta1
kind: AdvancedCronJob
metadata:
name: acj-image-pull
spec:
schedule: "0 */2 * * *"
concurrencyPolicy: Replace
template:
imageListPullJobTemplate:
spec:
parallelism: 5
images:
- nginx:1.14.2
- busybox:latest
pullSecrets:
- default-secret
selector:
names:
- node1
- node2
pullPolicy:
timeoutSeconds: 60
imagePullPolicy: IfNotPresent

This example creates an ImageListPullJob every 2 hours, pulling the specified images on node1 and node2. The concurrencyPolicy: Replace ensures that if a new job is triggered while the previous one is still running, the old one is replaced.

Limitation: Uses the v1beta1 API. The imageListPullJobTemplate field is available since v1.9.0.

CloneSet progressDeadlineSeconds​

In CI/CD pipelines, it is important to detect rollout failures early. Without a progress deadline, a stuck rollout (e.g., image pull errors, readiness probe failures) can hang indefinitely without any signal. v1.9.0 adds progressDeadlineSeconds to CloneSet, similar to the native Kubernetes Deployment field.

apiVersion: apps.kruise.io/v1beta1
kind: CloneSet
spec:
replicas: 10
progressDeadlineSeconds: 600
# ...

If the rollout does not progress within 600 seconds, the CloneSet controller adds the following condition to .status.conditions:

type: Progressing
status: "False"
reason: ProgressDeadlineExceeded

Higher-level orchestration systems (e.g., ArgoCD, Flux) can watch this condition to trigger automatic rollbacks.

Limitation: The value must be greater than spec.minReadySeconds. This condition does not stop the underlying rollout — it only signals the failure. Pausing the rollout also pauses the deadline check.

SidecarSet Dynamic Resources​

Sidecar containers (e.g., service mesh proxies, log agents) often need resources proportional to the main container. Previously, you had to set fixed resource requests/limits for sidecars, which led to either over-provisioning for small Pods or under-provisioning for large Pods.

v1.9.0 introduces resourcesPolicy, which lets you define sidecar resources as expressions based on the target Pod's container resources.

apiVersion: apps.kruise.io/v1beta1
kind: SidecarSet
spec:
containers:
- name: sidecar1
image: centos:6.7
resourcesPolicy:
targetContainersMode: sum
targetContainersNameRegex: ^large-engine-v4$
resourcesExpr:
limits:
cpu: max(cpu*50%, 50m)
memory: 200Mi
requests:
cpu: max(cpu*50%, 50m)
memory: 100Mi

In this example, the sidecar's CPU is set to 50% of the large-engine-v4 container's CPU, with a minimum of 50m. Supported expression operators include +, -, *, /, max(), min(), and Kubernetes resource quantities (e.g., 50m, 200Mi).

Limitation: The cpu and memory variables in the expression represent the aggregated resource values from target containers, calculated based on targetContainersMode (e.g., sum) and targetContainersNameRegex.

PodUnavailableBudget RESIZE Protection​

PodUnavailableBudget (PUB) protects application availability by limiting how many Pods can be unavailable simultaneously. Previously, PUB protected against DELETE, EVICT, and UPDATE operations. With the growing adoption of in-place vertical scaling (Kubernetes 1.27+ InPlacePodVerticalScaling), RESIZE operations can also make Pods temporarily unavailable.

v1.9.0 adds RESIZE as a protected operation. You can control which operations are protected via an annotation:

apiVersion: policy.kruise.io/v1alpha1
kind: PodUnavailableBudget
metadata:
name: web-server-pub
annotations:
# By default: DELETE, EVICT, UPDATE are protected
# Add RESIZE to also protect in-place resource resizing
kruise.io/pub-protect-operations: "DELETE, EVICT, UPDATE, RESIZE"
spec:
targetRef:
apiVersion: apps.kruise.io/v1beta1
kind: CloneSet
name: web-server
maxUnavailable: 20%

Limitation: If the InPlacePodVerticalScaling feature gate is disabled, in-place resizing is treated as an UPDATE operation instead.

Other Notable Changes​

The following features were also introduced in v1.9.0 — see the documentation for details:

  • SidecarSet shareVolumeDevicePolicy: Sidecar containers can now share block devices (VolumeDevices) with other containers in the Pod, analogous to the existing shareVolumePolicy for volume mounts.
  • SidecarSet injection order: SidecarSet now sorts containers and initContainers by name in ascending order during injection, ensuring deterministic ordering for sidecars with dependencies.
  • PodProbeMarker HTTP probe: Supports httpGet probes in addition to exec and tcpSocket, enabling direct HTTP health checks without wrapping curl in exec.
  • CloneSet OnDelete strategy: A new podUpdatePolicy type where Pods are only updated when manually deleted — useful for stateful workloads requiring manual update control.
  • JobSidecarTerminator exit code control: The KRUISE_TERMINATE_SIDECAR_IGNORE_EXIT_CODE env var lets you explicitly control whether a sidecar's non-zero exit code affects Pod Phase.
  • ImagePullJob node-side concurrency: The --max-concurrency flag on kruise-daemon limits concurrent image pulls per node, preventing resource exhaustion.
  • OpenKruise Daemon Windows support: kruise-daemon now runs on Windows nodes, enabling CRR, image pre-pulling, and PodProbeMarker for Windows workloads.

Other Improvements​

Various bug fixes and stability improvements are included in this release. For the full list, see the changelog.

What's Next in v2.0​

Looking ahead, the next major release (v2.0) will bring two significant changes:

More API upgrades to v1beta1: CloneSet, WorkloadSpread, UnitedDeployment, PersistentPodState, PodUnavailableBudget, PodProbeMarker, and NodePodProbe will be promoted from v1alpha1 to v1beta1. Additionally, the v1alpha1 API for Advanced StatefulSet will be removed in v2.0.

ConfigMapSet — a new configuration canary release feature: ConfigMapSet is a new CRD currently under active development on the master branch. It enables zero-downtime configuration updates decoupled from image releases — you can update configuration data (e.g., YAML files, environment variables) and roll it out gradually without rebuilding images. Key capabilities include:

  • Version management: Maintains a revision history of configuration versions, allowing rollback to previous versions.
  • Configuration canary: Uses partition in updateStrategy to control the rollout percentage, enabling gradual configuration updates.
  • Container selection: Supports both static container names and dynamic selection via field references (compatible with SidecarSet injection).
  • Update strategies: Two modes — injection-only (default) where the reload sidecar updates configs without restarting containers, and restartInjectedContainers mode where containers using the configuration are also restarted.
apiVersion: apps.kruise.io/v1alpha1
kind: ConfigMapSet
metadata:
name: deploy-cms
spec:
selector:
matchLabels:
app: sample
data:
settings.yaml: |
value: aaa
containers:
- name: main
mountPath: /data/conf
revisionHistoryLimit: 5
updateStrategy:
partition: 10%
restartInjectedContainers: true
maxUnavailable: 1

Note: ConfigMapSet is still under active development. The API and feature set may change before the official release.

Get Involved​

Welcome to get involved with OpenKruise by joining us in Github/Slack/DingTalk/WeChat. Have something you'd like to broadcast to our community? Share your voice at our Bi-weekly community meeting (Chinese), or through the channels below:

  • Join the community on Slack (English).
  • Join the community on DingTalk: Search GroupID 23330762 (Chinese).
  • Join the community on WeChat (new): Search User openkruise and let the robot invite you (Chinese).

OpenKruise Agents v0.3.0: Making Agent Sandboxes Truly Operatable

· 17 min read

Keywords: Batch Upgrade · Multi-Tenancy · In-Place VPA · Lifecycle Hook · E2B Compatible

As AI Agents move into large-scale production, Sandboxes — the runtime containers that host tool invocations, code interpreters, and long-running session workspaces — have rapidly evolved from "just make it work" to "make it fast, stable, and manageable." In 2025, the CNCF workload project OpenKruise incubated a sub-project dedicated to Agent scenarios — OpenKruise Agents, focused on solving delivery efficiency, resource governance, and operational challenges for AI Agent workloads on Kubernetes.

Recently, OpenKruise Agents officially released v0.3.0. This release brings significant enhancements across three dimensions: upgrade operations, multi-tenant governance, and cost optimization. The three most anticipated core features are: a complete upgrade pipeline for warm pool and claimed Sandboxes (SandboxUpdateOps batch upgrade CR + Recreate strategy + Lifecycle Hooks), a multi-tenant isolation and authorization system based on Teams and API Keys, and in-place CPU resizing (VPA) during the Claim phase.

This post is organized in two parts: Part One covers the overall positioning and core concepts of OpenKruise Agents to help newcomers get up to speed; Part Two dives into the three core features of v0.3.0 with YAML examples and scenario breakdowns, explaining their design motivation, mechanics, and usage.


Part One: What Is OpenKruise Agents and What Can It Do​

1.1 Project Positioning​

OpenKruise Agents provides best practices for managing AI agent workloads in Kubernetes.

OpenKruise Agents is an extension of OpenKruise for AI Agent scenarios, providing cloud-native workload abstractions and runtime governance for "sandboxed" agent workloads.

It is neither an Agent framework nor an LLM inference engine, but rather the "workload layer" for sandboxes themselves — bringing scenarios like E2B, AgentScope, Manus, OpenClaw, and Code Interpreter that require per-session/task isolated environments down to Kubernetes for unified scheduling, lifecycle management, and interface exposure. Its design goals cover four typical workload categories:

  • Isolated execution environments for diverse AI Agent tool invocations (Code Interpreter, Shell, Browser, etc.);
  • Network-accessible, persistent cloud development workspaces for Research Notebooks / Codespaces;
  • High-concurrency tasks in reinforcement learning for Human-in-the-loop and Open-world training;
  • Fast startup and fault recovery requirements for large-scale training tasks.

1.2 Key Capabilities Overview​

The core value of OpenKruise Agents can be summarized in four pillars:

First, ultra-fast delivery through resource pooling and dynamic scaling. By pre-creating a batch of idle Sandboxes in a Warm Pool, when an Agent request arrives it simply "claims" one from the pool, eliminating Pod startup time from the delivery path and achieving sub-second cold starts.

Second, Hibernation and Checkpointing. Sandboxes can be paused when idle to release CPU/memory, then resumed on demand; the Checkpoint CRD can take memory + filesystem snapshots of running Sandboxes and fork multiple identical replicas from them — essential for RL rollouts, debugging reproduction, and similar scenarios. (Note: This feature is currently available on Alibaba Cloud ACS; the open-source community version is being gradually released.)

Third, user identity, Teams, and traffic routing. Each Sandbox is not a bare Pod but a "user-level runtime" with Team / API Key isolation and efficient traffic proxying. This layer minimizes dependence on Kubernetes Services (which are not flexible enough and have quantity limits in sandbox scenarios).

Fourth, dual-protocol APIs. OpenKruise Agents provides both a Kubernetes CRD API (for platform engineers / SREs) and a fully E2B-compatible API (for ML engineers / upstream Agent frameworks). Teams already using the E2B SDK can connect to an OpenKruise Agents backend with zero code changes.

1.3 Core Concept Map​

Understanding OpenKruise Agents requires clarifying the relationships between several CRDs:

CRDShort NameRole
SandboxsbxCore resource representing a specific sandbox instance (typically backed by a Pod), supporting advanced lifecycle operations such as Create/Delete/Pause/Resume/Lifecycle
SandboxSetsbsWorkload that manages a batch of homogeneous Sandboxes (analogous to ReplicaSet for Pods), primarily responsible for maintaining the warm pool and serving as the Sandbox template
SandboxTemplate—Immutable template version snapshot. SandboxSet derives a SandboxTemplate when the template changes, used for version tracing
SandboxClaimsbcA "claim request" issued against a SandboxSet — claims an unused Sandbox from the warm pool and performs post-processing such as in-place image replacement, dynamic storage mounting, and in-place VPA CPU resizing
CheckpointcpRuntime state snapshot of a Sandbox (memory + rootfs), which can be used to fork multiple new instances
SandboxUpdateOpssuoNew in v0.3.0, batch upgrade operations targeting "claimed" Sandboxes

The data flow connects as follows: Platform administrators define a SandboxSet → the controller maintains a certain number of Sandboxes in available state within the warm pool → Agents claim Sandboxes via the E2B SDK or SandboxClaim CR → claimed Sandboxes can be Paused/Resumed, Checkpointed, or upgraded via SandboxUpdateOps, and are eventually reclaimed upon completion or timeout.

1.4 Architecture Overview​

alt

OpenKruise Agents has a clear separation between the control plane and data plane, consisting of four components:

  • sandbox-manager: A stateless backend service that exposes E2B API and MCP API externally, serving as the entry point for SDKs and external Agent frameworks;
  • sandbox-gateway: A lightweight gateway built on Envoy filters that precisely routes inbound traffic to specific Pods by namespace + sandbox name + port, minimizing dependence on K8s Services;
  • sandbox-controller: A set of controllers responsible for reconciling CRDs such as SandboxSet / SandboxClaim / SandboxUpdateOps, and hosting related admission webhooks;
  • agent-runtime: Injected as a sidecar into Sandbox Pods, providing E2B envd-compatible command and file operations, dynamic CSI mounting, Lifecycle Hook script execution, and other runtime capabilities.

This layered design enables OpenKruise Agents to seamlessly integrate with the E2B ecosystem "upward" while fully leveraging native K8s workload capabilities "downward" (rolling updates, Pod topology awareness, PVC, CSI, etc.).

1.5 Relationship with E2B​

E2B is the most widely used open-source Sandbox SDK in the AI Agent space, offering Python / JavaScript clients. The sandbox-manager in OpenKruise Agents supports both the native E2B protocol and extended protocols:

from e2b_code_interpreter import Sandbox

# Standard E2B usage — runs on OpenKruise Agents cluster with zero modifications
with Sandbox.create(template="demo") as sbx:
print(sbx.get_info())

# Use OpenKruise Agents enhanced capabilities via extended metadata
sbx = Sandbox.create(template="demo", metadata={
# In-place image replacement: replace the default warm pool image with a specific version at claim time
"e2b.agents.kruise.io/image": "my-registry/sandbox:v2",
# In-place CPU resizing (VPA): adjust resources on demand without Pod recreation
"e2b.agents.kruise.io/cpu-request": "2000m",
"e2b.agents.kruise.io/cpu-limit": "4",
# Dynamic storage mounting: automatically mount persistent volumes at claim time
"e2b.agents.kruise.io/csi-volume-config": '[{"pvName":"nas-pv-sandbox-system","mountPath":"/data-nas","subPath":"data-subPath"},{...}]',
})

Here, template="demo" corresponds to a SandboxSet named demo. Standard E2B code runs without any modifications; through e2b.agents.kruise.io/* extended metadata, image replacement, resource resizing, and storage mounting can all be completed in a single claim operation without additional API calls.

In other words, OpenKruise Agents embraces E2B's application semantics while transforming the underlying infrastructure into workloads that K8s platform teams can govern. Teams with existing E2B code get a near drop-in replacement; platform teams gain the full cloud-native toolchain including rolling upgrades, Quotas, Sidecar injection, and dynamic PV mounting.


Part Two: v0.3.0 Key Features: Upgrade Operations, Cost Optimization, and Multi-Tenant Governance​

If previous versions addressed "how to deliver Sandboxes quickly," then the core theme of v0.3.0 is "after delivery, how to manage, use, and upgrade them well" — batch upgrades make Sandbox versions controllable and convergent, VPA enables on-demand resource allocation without waste, and multi-tenancy brings clear accountability to shared clusters.

2.1 Background: Why Upgrading Claimed Sandboxes Is So Hard​

A cluster typically contains two types of Sandboxes simultaneously:

  • Unassigned Sandboxes: Idle instances residing in the SandboxSet warm pool that have not yet been claimed;
  • Claimed Sandboxes: Active instances that have been claimed by Agents and are carrying user sessions or long-running tasks.

Upgrading the former is straightforward — modify the SandboxSet's spec.template and the controller performs a rolling replacement based on maxUnavailable. The real challenge lies with the latter:

  • These Sandboxes carry user state (workspace files, model caches, long session contexts) and cannot be simply kubectl delete pod'd;
  • They are managed directly by the Sandbox CRD, not belonging to any ReplicaSet/Deployment, and native K8s lacks a mechanism to "batch upgrade a set of independent Sandboxes";
  • Upgrades inevitably involve Pod recreation (changing images, resources, volumes, etc.), meaning IP changes, in-memory state loss, and rootfs writable layer loss — the application layer needs explicit hook points to perform "backup → recreate → restore."

v0.3.0 delivers two complementary features for upgrade operations: SandboxUpdateOps batch upgrade CR and Recreate strategy + Lifecycle Hooks.

2.2 SandboxUpdateOps: Batch Upgrade CR for Claimed Sandboxes​

SandboxUpdateOps (short name suo) is a new CRD introduced in v0.3.0 with a clear purpose: dispatch upgrade tasks to a batch of claimed, running Sandboxes in one shot.

Design Model​

Comparable to a Kubernetes Job — one-time, with a well-defined target set and terminal state. It consists of three core configuration blocks:

  1. selector: Selects the target Sandbox set via Labels (supporting matchLabels / matchExpressions), typically batch-selecting a category of Sandboxes by the agents.kruise.io/sandbox-template=<sandboxset-name> label;
  2. updateStrategy.maxUnavailable: The maximum number of Sandboxes that can be upgrading simultaneously, supporting absolute values or percentages, defaulting to 1 — this is the core knob for canary upgrades;
  3. patch: Applied to each Sandbox's spec.template as a Strategic Merge Patch, carrying the change payload — can replace images, add/remove Volumes, adjust environment variables, etc.

Minimal working example:

apiVersion: agents.kruise.io/v1alpha1
kind: SandboxUpdateOps
metadata:
name: upgrade-my-sandboxes
namespace: default
spec:
selector:
matchLabels:
agents.kruise.io/sandbox-template: my-sandbox-pool
updateStrategy:
maxUnavailable: 2
patch:
spec:
containers:
- name: sandbox
image: my-registry/sandbox-image:v2

Key Constraints​

  • Only one Updating SandboxUpdateOps is allowed per Namespace at a time — to prevent interference between multiple tasks, a new one can only be initiated after the previous one completes or is deleted;
  • Only upgrades Sandboxes with Phase of Running or Upgrading; hibernating or waking instances are not supported;
  • SandboxUpdateOps is a one-time task — if it fails, it must be deleted and recreated (consistent with Job semantics);
  • Only applicable to Claimed Sandboxes; unassigned Sandboxes in the warm pool follow the SandboxSet's updateStrategy.

Observability and Status​

Upgrade progress can be viewed intuitively via kubectl get suo:

NAME                    PHASE      TOTAL   UPDATED   UPDATING   FAILED   AGE
upgrade-my-sandboxes Updating 1000 66 100 0 2m32s
  • PHASE: Pending / Updating / Completed / Failed
  • TOTAL: Total number of Sandboxes selected by the selector
  • UPDATED: Number of successfully upgraded Sandboxes
  • UPDATING: Number currently being upgraded (bounded by maxUnavailable)
  • FAILED: Number of failed upgrades

Each upgraded Sandbox is labeled with agents.kruise.io/update-ops=<suo-name> for easy filtering by UpdateOps:

kubectl get sandbox -l agents.kruise.io/update-ops=upgrade-my-sandboxes

2.3 Recreate Upgrade Strategy + Lifecycle Hooks: Preserving Data Through Pod-Recreating Upgrades​

SandboxUpdateOps is the "task orchestration layer," while Recreate strategy + Lifecycle Hooks form the "execution layer" for individual Sandbox upgrades. Together, they constitute the core of the v0.3.0 upgrade pipeline.

Upgrade Flow​

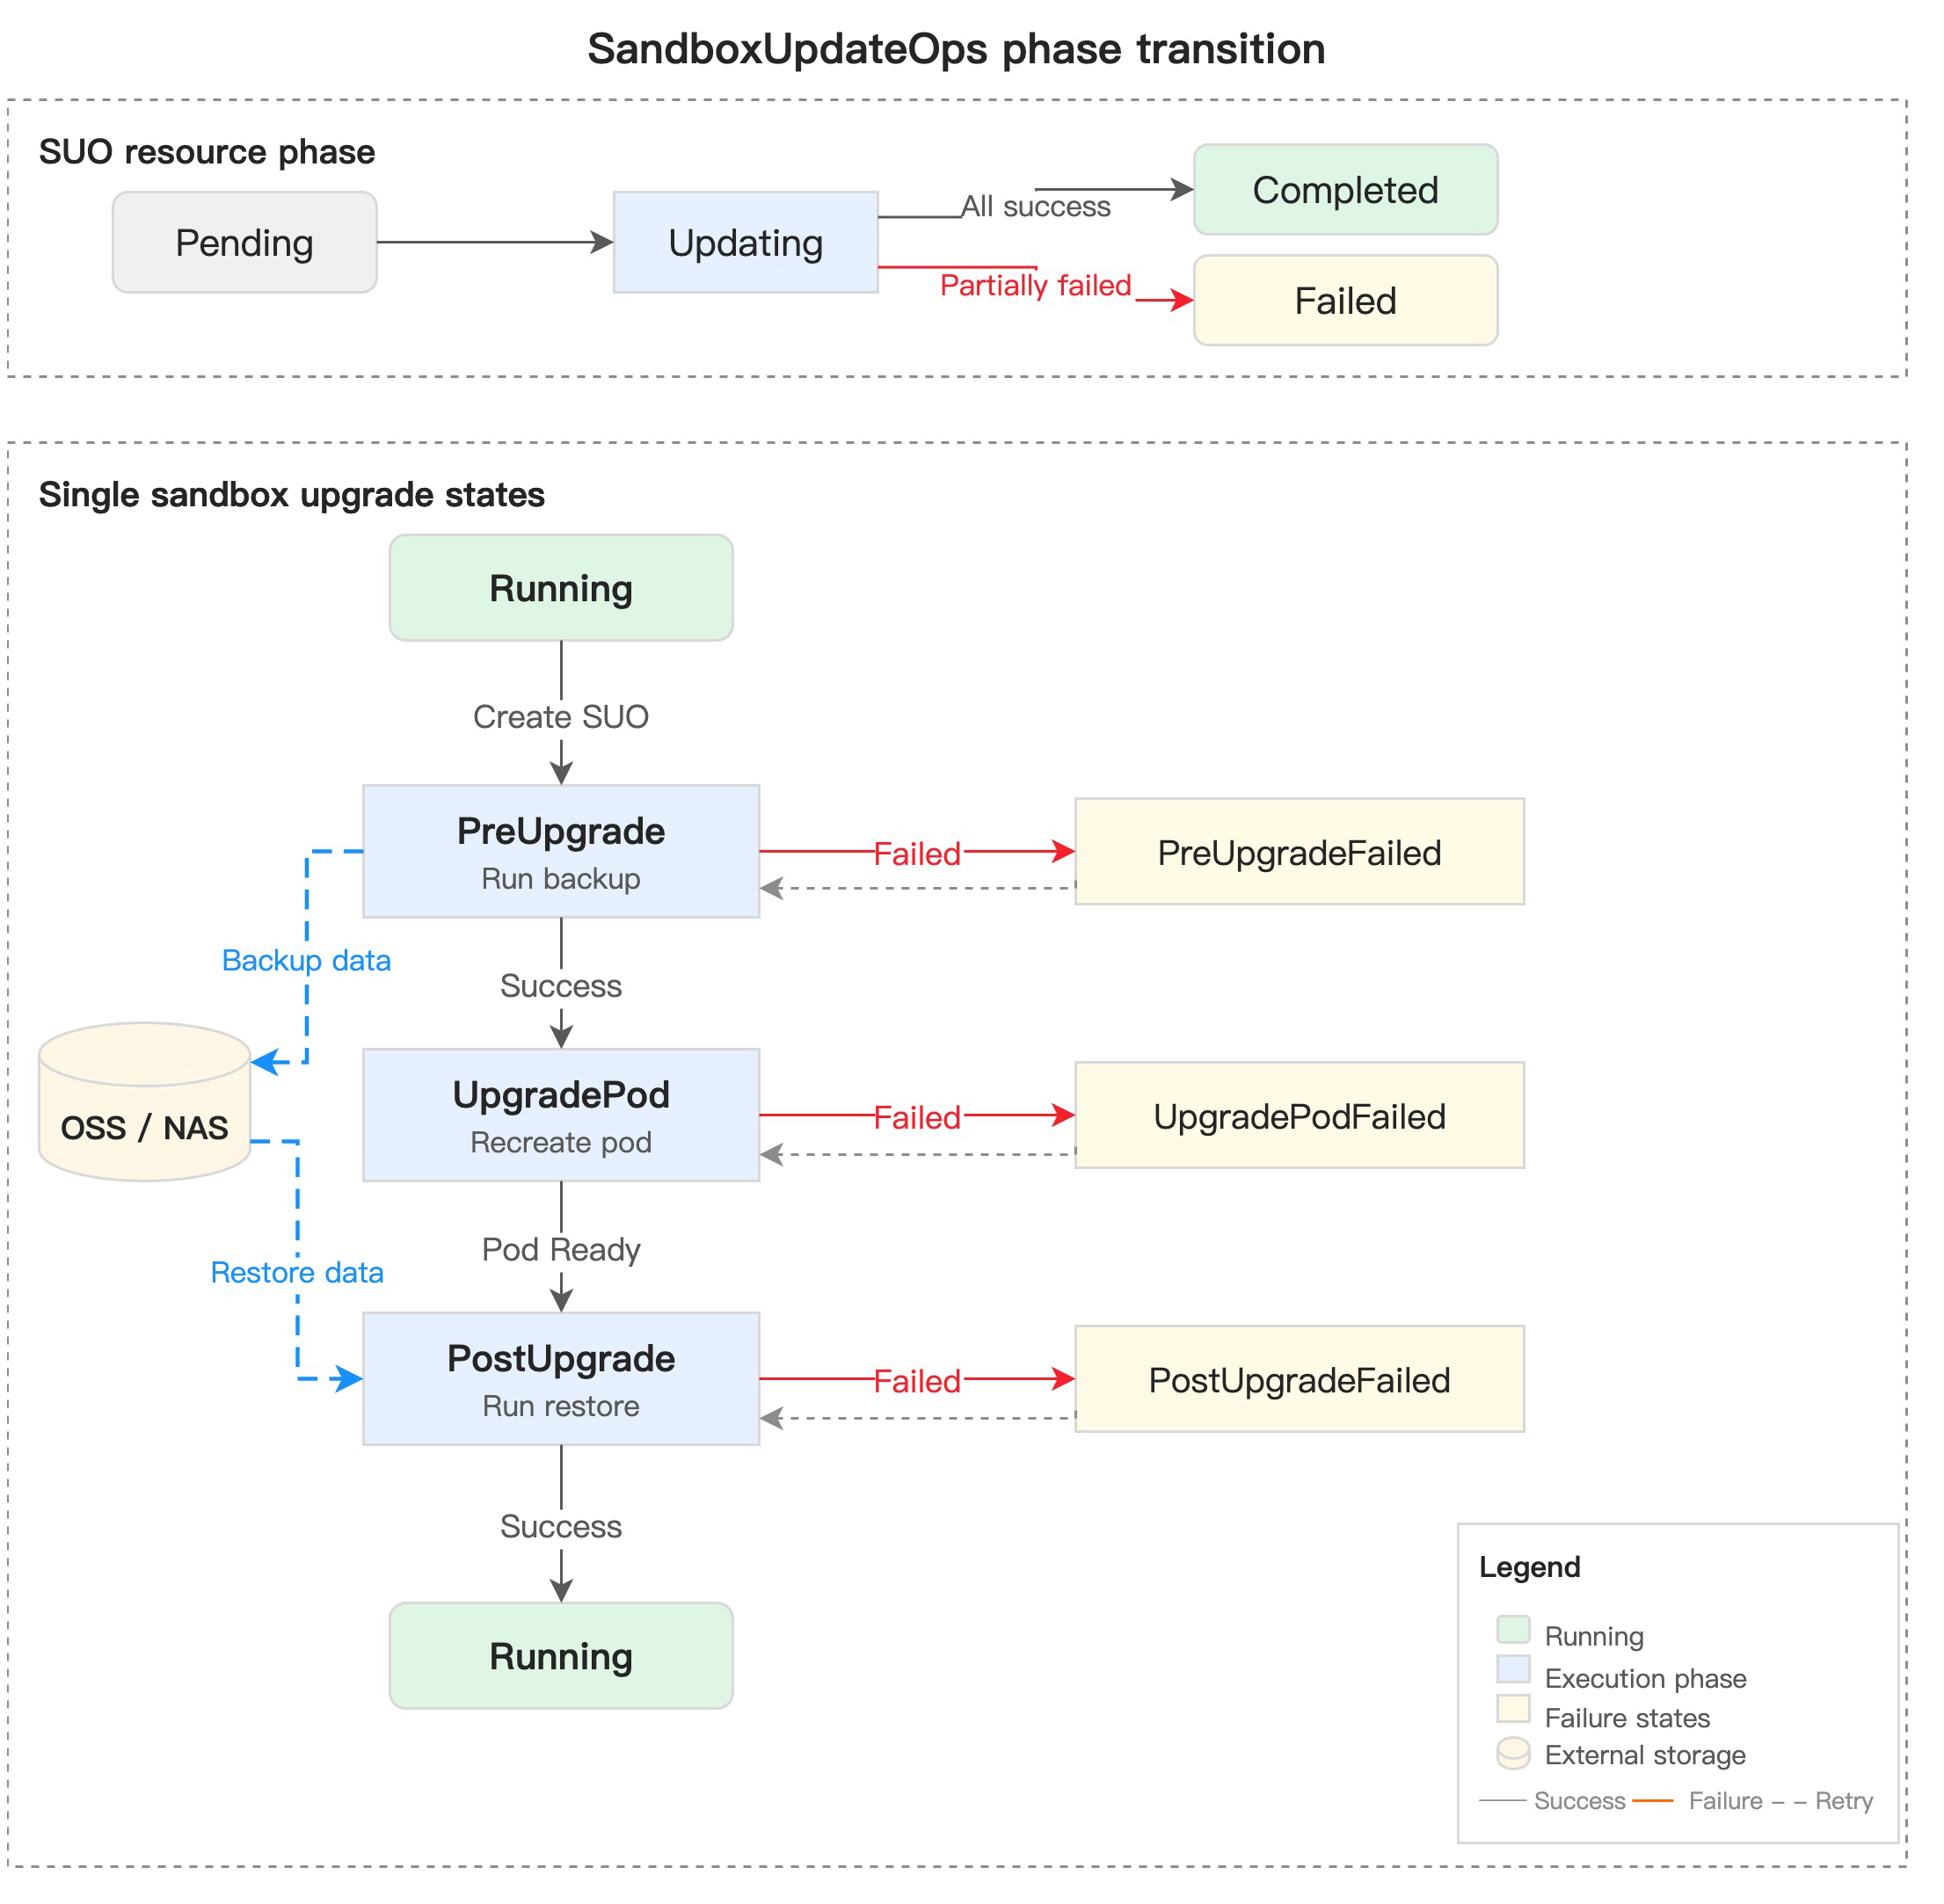
As shown in the diagram below, the Recreate strategy breaks down a single Sandbox upgrade into three strictly sequential phases: PreUpgrade (run backup scripts to write data to OSS / NAS) → UpgradePod (delete the old Pod and recreate with the new template) → PostUpgrade (restore data from external storage). Any phase failure halts the process and transitions to the corresponding Failed state.

alt

The strategy is called Recreate because the upgrade path must recreate the underlying Pod (changing images, resources, or mounts cannot be done purely in-place). Pod recreation means IP changes, in-memory state wipe, and rootfs writable layer loss — so OpenKruise Agents provides a hook before and after the recreation, allowing users to handle data backup and restoration themselves.

preUpgrade / postUpgrade Hooks​

  • preUpgrade: Executed before the old Pod is destroyed. Typical use: package and back up the working directory, long session contexts, model caches, etc. to persistent storage like OSS / NAS;
  • postUpgrade: Executed after the new Pod is Ready. Typical use: restore backup data from persistent storage to the working directory.

Hook execution depends on two sidecars:

  • agent-runtime: Provides E2B envd-compatible command execution capability; all Hook scripts ultimately run inside the Sandbox through it;
  • csi: Dynamic mounting capability; must be injected if backup/restore needs to write to OSS / NAS.

Here is a complete example — packaging the OpenClaw workspace .openclaw to a dynamically mounted OSS directory /backup before upgrade, and restoring it afterward:

apiVersion: agents.kruise.io/v1alpha1
kind: SandboxUpdateOps
metadata:
name: upgrade-with-backup
namespace: default
spec:
selector:
matchLabels:
agents.kruise.io/sandbox-template: openclaw-sbs
updateStrategy:
maxUnavailable: 10%
patch:
spec:
containers:
- name: gateway
image: ghcr.io/openclaw/openclaw:2026.4.11 # New version image
lifecycle:
preUpgrade:
exec:
command:
- /bin/bash
- -c
- |
set -e
cd /root/
tar -czf openclaw-state-v1.tgz .openclaw
mv openclaw-state-v1.tgz /backup
echo 'preUpgrade success'
timeoutSeconds: 600
postUpgrade:
exec:
command:
- /bin/bash
- -c
- |
set -e
rm -rf /root/.openclaw
cp /backup/openclaw-state-v1.tgz /root/openclaw-state-v1.tgz
tar -xzvf /root/openclaw-state-v1.tgz -C /root
rm -rf /root/openclaw-state-v1.tgz
timeoutSeconds: 600

Fine-Grained State Machine: Pinpointing Each Sandbox's Failure Point​

During the upgrade process, a Sandbox is in Phase=Upgrading, with the current stage exposed via status.conditions[type=Upgrading].reason:

ReasonDescription
PreUpgradeExecuting the preUpgrade script
PreUpgradeFailedpreUpgrade script execution failed
UpgradePodRecreating the Pod with the new template
UpgradePodFailedNew Pod startup failed (image pull failure, startup timeout, crash, etc.)
PostUpgradeExecuting the postUpgrade script
PostUpgradeFailedpostUpgrade script execution failed
SucceededUpgrade completed

This design makes troubleshooting highly intuitive — kubectl get sandbox <name> -o yaml to inspect conditions immediately reveals which stage is stuck and the specific error message. Remediation strategies after failure:

  • PreUpgrade failure: The underlying container is untouched; data is safe. Fix the script or rollback the patch;
  • UpgradePod failure: The old Pod has been destroyed but the new Pod is not up. Use Checkpoint to recover, or rollback the patch to the old image. Note that preUpgrade has already executed at this point; when retrying, you must remove preUpgrade to avoid duplicate backups;
  • PostUpgrade failure: The new Pod is ready but the restore script failed. Fix the script and create a new SandboxUpdateOps with only postUpgrade to retry.

Pausing an In-Progress Upgrade​

If issues are discovered during an upgrade and you need to "hit the brakes," simply set paused: true:

spec:
paused: true

This only prevents new Sandboxes from entering the upgrade queue; Sandboxes already being upgraded will continue through their existing workflow.

2.4 In-Place CPU Resize: Pre-warm at Minimal Specs, Scale Up On Demand at Claim Time​

Problem Statement​

The core value of the warm pool is "fast startup" — pre-creating Sandboxes so that when a request arrives, it can be claimed immediately, bypassing Pod startup time. From a cost perspective, the warm pool should use minimal specs (e.g., 0.5C1G) to reduce idle resource consumption. However, in practice, different Agent tasks have vastly different resource requirements — data analysis may need 4 cores, while local LLM inference may require 8 cores.

Previous approaches each had drawbacks: maintaining a separate SandboxSet for each spec tier (scattered pools, management complexity); pre-warming uniformly at the maximum spec (severe resource waste when idle); recreating Pods to adjust specs after claiming (completely negating the warm pool advantage).

v0.3.0 leverages native Kubernetes In-Place Pod Vertical Scaling to perform "in-place resizing" on warm pool Sandboxes during the Claim phase — no Pod recreation, no IP change, no container restart, only CPU requests/limits are adjusted. This preserves the warm pool's sub-second delivery while satisfying the need for differentiated on-demand configuration.

Usage: Dual-Protocol via E2B and SandboxClaim​

Via E2B SDK (using extended metadata):

from e2b_code_interpreter import Sandbox

sbx = Sandbox.create(template="demo", metadata={
"e2b.agents.kruise.io/cpu-request": "1000m",
"e2b.agents.kruise.io/cpu-limit": "2"
})

Via SandboxClaim CR declaratively:

apiVersion: agents.kruise.io/v1alpha1
kind: SandboxClaim
metadata:
name: demo-sandbox-claim
namespace: default
spec:
templateName: demo
inplaceUpdate:
resources:
requests:
cpu: "1000m"
limits:
cpu: "2"

Usage Constraints​

  • Currently only CPU resize is supported; memory and other resources are ignored;
  • Only applies to the main container (sidecars are unchanged);
  • Resizing must not change the Pod's QoS class (e.g., downgrading from Guaranteed to Burstable will be rejected);
  • Requires Kubernetes in-place pod resize — K8s 1.33+ is recommended (the feature is beta and enabled by default); K8s 1.27–1.32 requires manually enabling the InPlacePodVerticalScaling feature gate;
  • This capability is controlled by the SandboxInPlaceResourceResize feature gate, which is enabled by default on the OpenKruise Agents side;
  • Can be combined with image replacement at claim time (inplaceUpdate.image) — swap images and resize resources in a single claim.

2.5 Team-Based Multi-Tenant Isolation and API Key Authorization​

v0.3.0 introduces a complete multi-tenant authorization model, providing clear isolation boundaries for multi-team shared clusters in production environments.

Core design: Team Name = Kubernetes Namespace. Each Team's identity is uniquely identified by its Team Name, which maps directly to an existing Kubernetes Namespace. This means the Namespace's inherent isolation naturally becomes the Sandbox's authorization boundary — no additional isolation abstractions needed; tenants can only operate on resources within their own Namespace.

Two-level role model:

RoleScope
Admin (admin Team)Cluster-level permissions: issue/revoke API Keys for any Team, view all Teams and Sandboxes
Regular TenantNamespace-level permissions: manage their own Team's Keys, can only access Sandboxes created by their own Keys

The built-in admin API Key is initialized when sandbox-manager starts and cannot be deleted for cluster controllability.

API Key as identity credential. When clients call any sandbox-manager endpoint, they carry credentials via the X-API-KEY request header. An API Key determines three things: which Team the caller belongs to, whether they are an admin, and which Sandboxes they can access. sandbox-manager provides a set of E2B-compatible HTTP endpoints (GET/POST/DELETE /api-keys, GET /teams) for full Key lifecycle management.

Pluggable Key storage backends. API Key persistence supports two backends, switched via the --e2b-key-storage parameter:

  • secret (default): A zero-dependency approach that stores all Keys in a Kubernetes Secret, suitable for trials or single-tenant scenarios (recommended Key count ≤ 500);
  • mysql: Persists to MySQL via GORM, storing only HMAC-SHA256 hashes, never plaintext. Suitable for multi-tenant, multi-replica production deployments with shared Key storage and no capacity bottleneck.

A typical multi-tenant workflow: Cluster admin uses the admin Key to issue the first API Key for each Team → tenants use their own Key to self-service create additional Keys (e.g., a CI Runner-specific Key) → tenants create and manage Sandboxes within their own Namespace via Keys → admins can globally observe and govern resource usage across all Teams.


Part Three: Roadmap and Community​

With v0.3.0 completing the "upgrade operations" puzzle, the community's next phase will focus on:

  • Traffic Management and Security Policies (#433): Introducing TrafficPolicy / GlobalTrafficPolicy (L3/L4) and SecurityProfile (L7) CRDs to provide fine-grained egress traffic control for Sandboxes — supporting IP/port-level allow-deny rules, as well as L7 policies based on HTTP host/path/method (interception, rate limiting, identity injection, traffic mirroring, etc.);
  • Security Identity Integration (Proposal): Introducing a pluggable Gateway Identity Provider framework that, when Sandboxes access external services through the gateway, issues access tokens bound to the Sandbox/Agent from an external identity service and automatically performs credential substitution at the gateway layer — supporting automatic token refresh, mTLS authentication, and graceful degradation (falling back to UUID tokens when the identity service is unavailable to avoid blocking delivery);

If you are building an AI Agent platform, Code Interpreter service, long-session Codespace, reinforcement learning training framework, or looking for a cloud-native foundation for your team's E2B deployment, feel free to star openkruise/agents, and join the community through:

OpenKruise Agents v0.3.0 is now available on GitHub Releases and major container registries. We look forward to your feedback and Pull Requests.
A Flexible and Configurable Serverless Elastic Solution at the Workload Level

· 13 min read
Tianyun Zhong
Member of OpenKruise

Serverless represents an extension of cloud computing, inheriting its most significant feature: on-demand elastic scaling. This model design allows developers to focus on application logic without concerning themselves with deployment resources, thereby fully leveraging resource scalability to provide superior elasticity capabilities. Enterprises can also genuinely benefit from true pay-as-you-go characteristics. Consequently, more cloud providers are converging towards this new architectural paradigm.

The core capability of "flexible configurability" in Serverless technology focuses on enabling specific cloud usage scenarios to fully utilize cloud resources through simple, minimally invasive, and highly configurable methods. Its essence lies in resolving the conflict between capacity planning and actual cluster load configuration. This article will sequentially introduce two configurable components — WorkloadSpread and UnitedDeployment — discussing their core capabilities, technical principles, advantages and disadvantages, as well as real-world applications. Through these discussions, we aim to share OpenKruise's technical evolution and considerations in addressing Serverless workload elasticity.

Overview of Elastic Scenarios

As Serverless technology matures, more enterprises prefer using cloud resources (such as Alibaba Cloud ACS Serverless container instances) over on-premise resources (like managed resource pools or on-premise IDC data centers) to host applications with temporary, tidal, or bursty characteristics. This approach enhances resource utilization efficiency and reduces overall costs by adopting a pay-as-you-go model. Below are some typical elastic scenarios:

  1. Prioritize using on-premise resources in offline IDC data centers; scale application to the cloud when resources are insufficient.
  2. Prefer using pre-paid resource pool in the cloud; use pay-as-you-go Serverless instances for additional replicas when resources are insufficient.
  3. Use high-quality stable compute power (e.g., dedicated cloud server instances) first; then use lower-quality compute power (e.g., Spot instances).
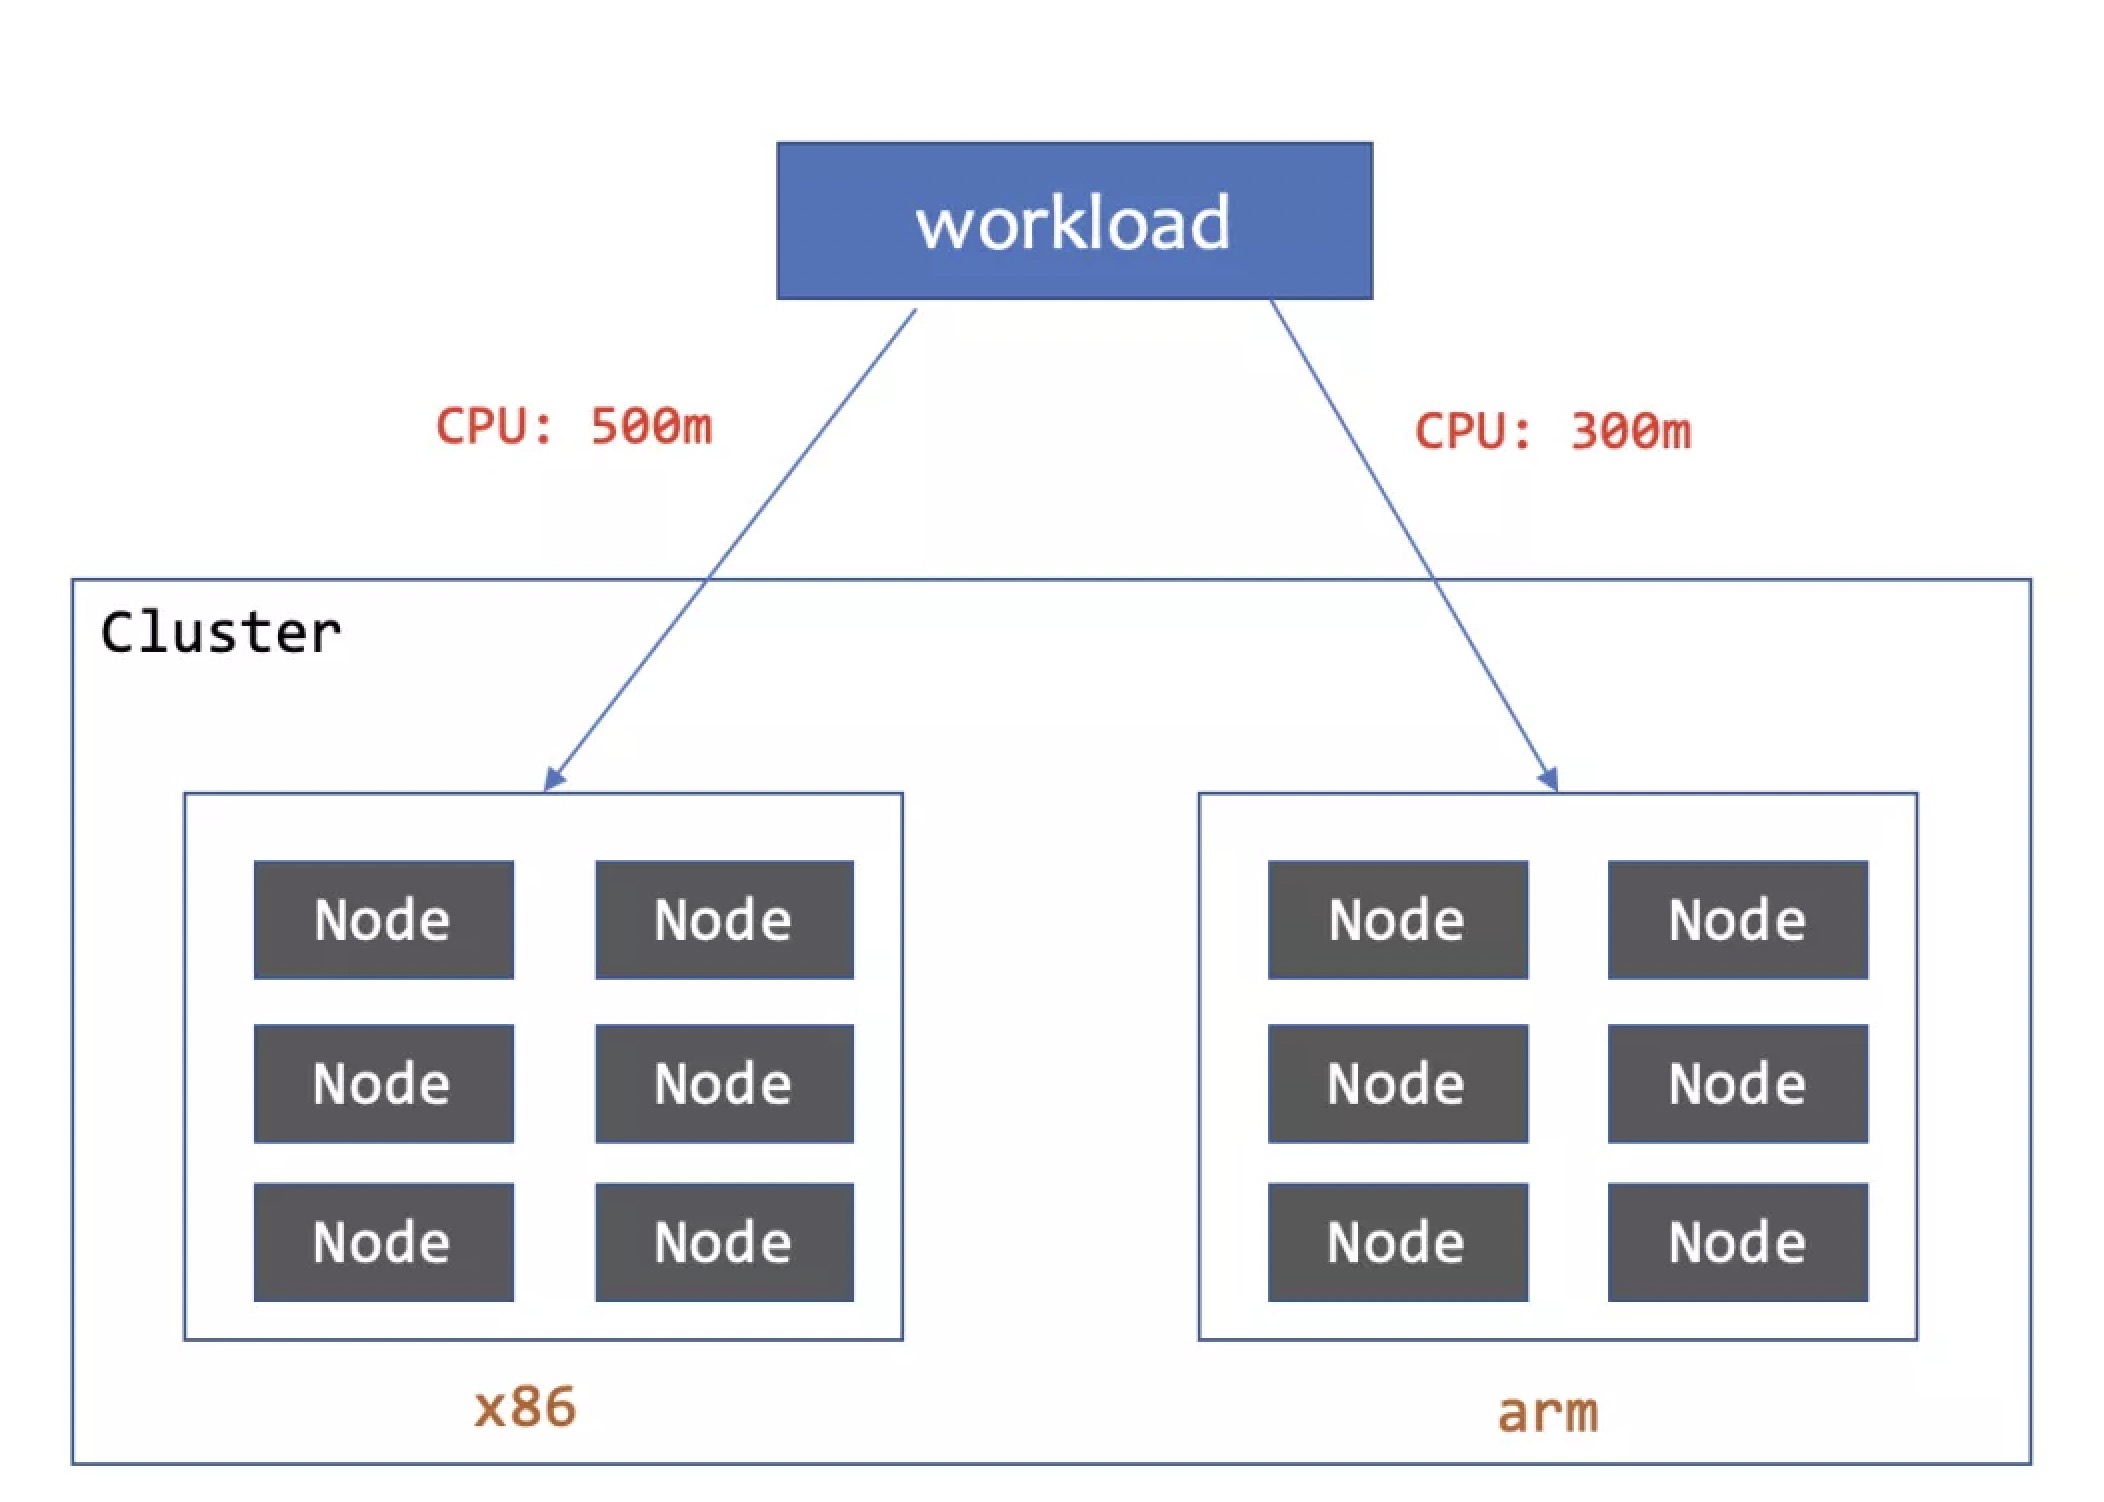
  4. Configure different resource quantities for container replicas deployed on different compute platforms (e.g., X86, ARM, Serverless instances) to achieve similar performance.
  5. Inject different middleware configurations into replicas deployed on nodes versus Serverless environments (e.g., shared Daemon on nodes, Sidecar injection on Serverless).

These components introduced in this article offer distinct advantages in solving the above problems. Users can choose appropriate capabilities based on their specific scenarios to effectively leverage elastic compute power.

Capabilities and Advantageous Scenarios of Two Components

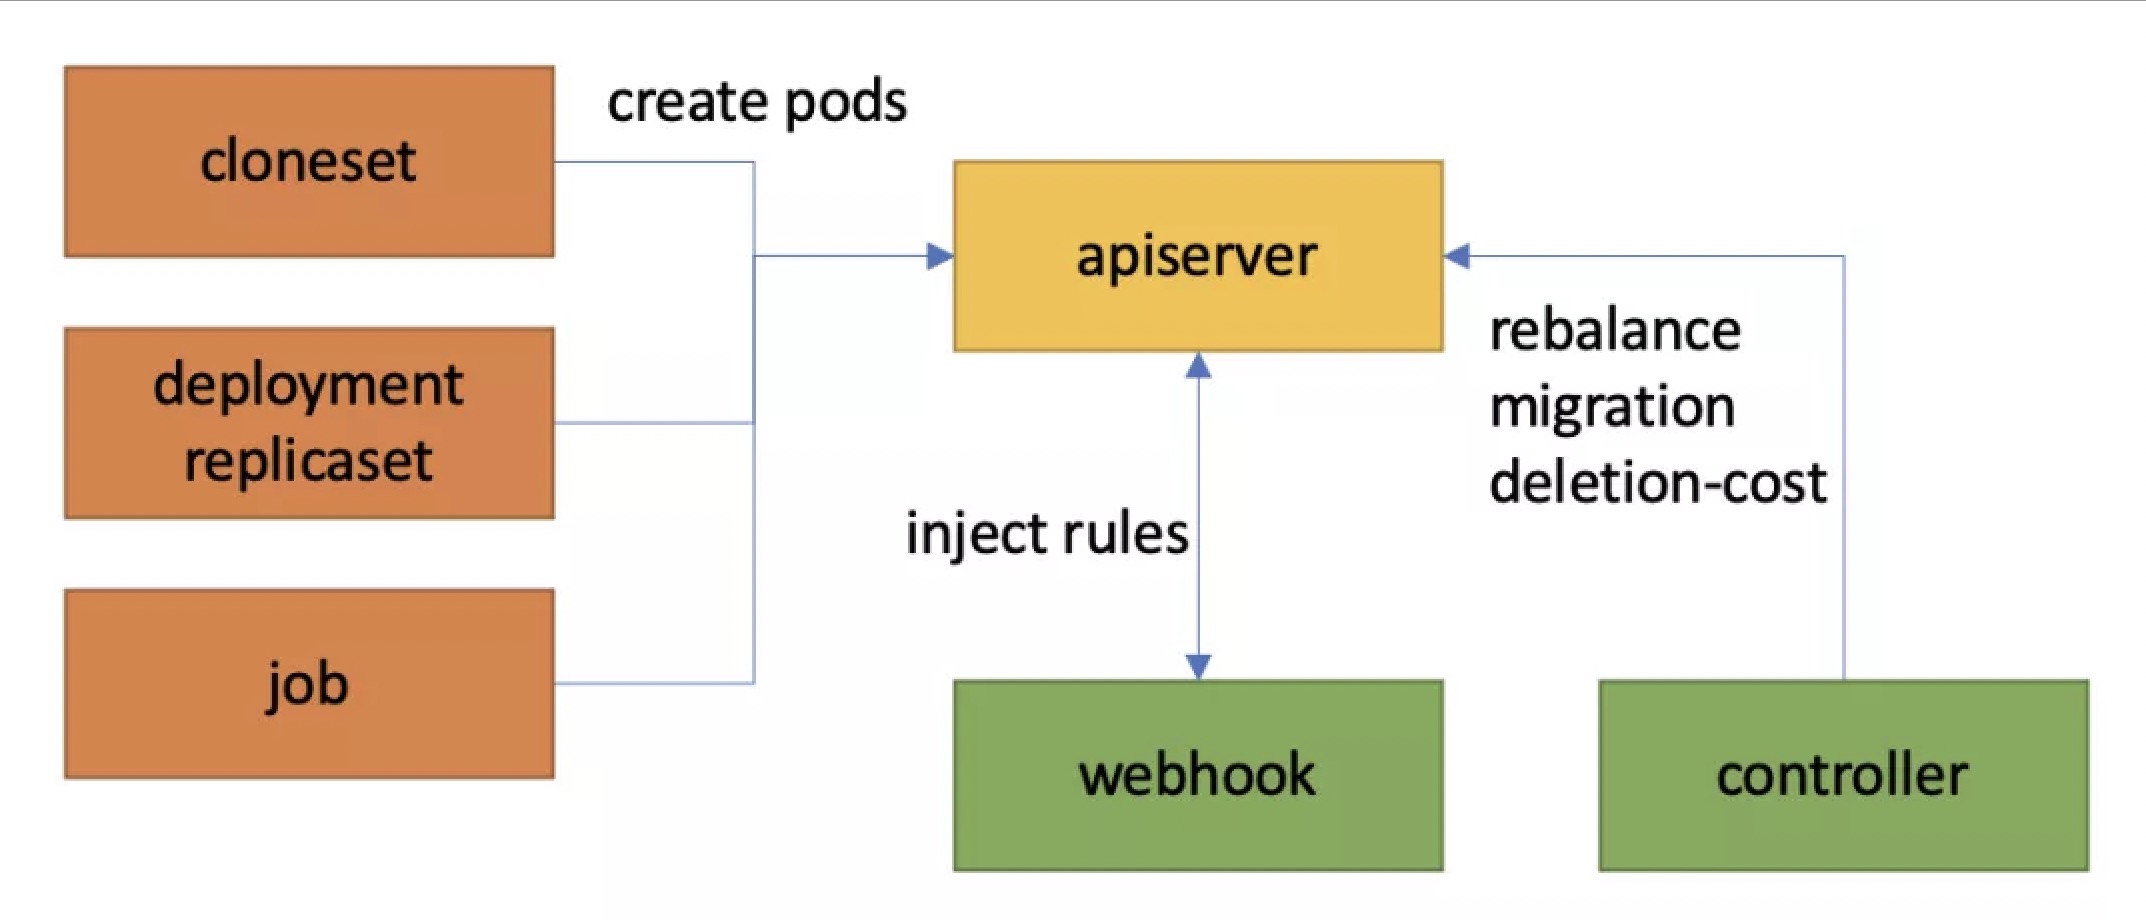
  • WorkloadSpread: Utilizes a Mutating Webhook to intercept Pod creation requests that meet certain criteria and apply Patch operations to inject differentiated configurations. Suitable for existing applications requiring multiple elastic partitions with customized Pod Metadata and Spec fields.
  • UnitedDeployment: A workload with built-in capability of elastic partitioning and pod customization, offering stronger elasticity and capacity planning capabilities. Ideal for new applications needing detailed partitioning and individual configurations for each partition.

WorkloadSpread: An Elastic Strategy Plugin Based on Pod Mutating Webhook

WorkloadSpread is a bypass component provided by the OpenKruise community that spreads target workload Pods across different types of subsets according to specific rules, enhancing multi-region and elastic deployment capabilities without modifying the original workload. It supports almost all native or custom Kubernetes workloads, ensuring adaptability and flexibility in various environments.

Example Configuration​

apiVersion: apps.kruise.io/v1alpha1
kind: WorkloadSpread
metadata:
name: workloadspread-demo
spec:
targetRef: # Supports almost all native or custom Kubernetes workloads
apiVersion: apps/v1 | apps.kruise.io/v1alpha1
kind: Deployment | CloneSet
name: workload-xxx
subsets:
- name: subset-a
# The first three replicas will be scheduled to this Subset
maxReplicas: 3
# Pod affinity configuration
requiredNodeSelectorTerm:
matchExpressions:
- key: topology.kubernetes.io/zone
operator: In
values:
- zone-a
patch:
# Inject a custom label to Pods scheduled to this Subset
metadata:
labels:
xxx-specific-label: xxx
- name: subset-b
# Deploy to Serverless clusters, no capacity and unlimited replicas
requiredNodeSelectorTerm:
matchExpressions:
- key: topology.kubernetes.io/zone
operator: In
values:
- acs-cn-hangzhou
scheduleStrategy:
# Adaptive mode will reschedule failed Pods to other Subsets
type: Adaptive | Fixed
adaptive:
rescheduleCriticalSeconds: 30

Powerful Partitioning Capability​

WorkloadSpread spreads Pods into different elastic partitions using Subsets, scaling up forward and scaling down backward based on Subset order.

Flexible Scheduling Configuration​

At the Subset level, WorkloadSpread supports selecting nodes via Labels and configuring advanced options such as taints and tolerations. For example, requiredNodeSelectorTerm specifies mandatory node attributes, preferredNodeSelectorTermssets preferred node attributes, and tolerations configures Pod tolerance for node taints. These configurations allow precise control over Pod scheduling and distribution.

At the global level, WorkloadSpread supports two scheduling strategies via the scheduleStrategy field: Fixed and Adaptive. The Fixed strategy ensures strict adherence to predefined Subset distributions, while the Adaptive strategy provides higher flexibility by automatically rescheduling Pods to other available Subsets when necessary.

Detailed Pod Customization​

In Subset configurations, the patch field allows for fine-grained customization of Pods scheduled to that subset. Supported fields include container images, resource limits, environment variables, volume mounts, startup commands, probe configurations, and labels. This decouples Pod specifications from environment adaptations, enabling flexible workload adjustments for various partition environments.

...
# patch pod with a topology label:
patch:
metadata:
labels:
topology.application.deploy/zone: "zone-a"
...

The example above demonstrates how to add or modify a label to all Pods in a Subset.

...
# patch pod container resources:
patch:
spec:
containers:
- name: main
resources:
limit:
cpu: "2"
memory: 800Mi
...

The example above demonstrates how to add or modify the Pod Spec.

...
# patch pod container env with a zone name:
patch:
spec:
containers:
- name: main
env:
- name: K8S_AZ_NAME
value: zone-a
...

The example above demonstrates how to add or modify a container environment variable.

WorkloadSpread's Pod Mutating Webhook Mechanism​

WorkloadSpread operates directly on Pods created by the target workload via Pod Mutating Webhook, ensuring non-intrusive operation. When a Pod creation request meets the criteria, the Webhook intercepts it, reads the corresponding WorkloadSpread configuration, selects an appropriate Subset, and modifies the Pod configuration accordingly. The controller maintains the controller.kubernetes.io/pod-deletion-cost label to ensure correct downsizing order.

Limitations of WorkloadSpread​

Potential Risks of Webhook​

WorkloadSpread depends on Pod Mutating Webhook to function, which intercepts all Pod creation requests in the cluster. If the Webhook Pod (kruise-manager) experiences performance issues or failures, it may prevent new Pods from being created. Additionally, during large-scale scaling operations, Webhook can become a performance bottleneck.

Limitations of Acting on Pods​

While acting on Pods reduces business intrusion, it introduces limitations. For instance, CloneSet's gray release ratio cannot be controlled per Subset.

Case Study 1: Bandwidth Package Allocation in Large-Scale Load Testing​

A company needed to perform load testing before a major shopping festival. They developed a load-agent program to generate requests and used a CloneSet to manage agent replicas. To save costs, they purchased 10 shared bandwidth packages (each supporting 300 Pods) and aimed to dynamically allocate them to elastic agent replicas.

They configured a WorkloadSpread with 11 Subsets: the first 10 Subsets had a capacity of 300 and patched Pod Annotations to bind specific bandwidth packages; the last Subset had no capacity and no bandwidth package, preventing extra bandwidth allocation if more than 3000 replicas were created.

apiVersion: apps.kruise.io/v1alpha1
kind: WorkloadSpread
metadata:
name: bandwidth-spread
namespace: loadtest
spec:
targetRef:
apiVersion: apps.kruise.io/v1alpha1
kind: CloneSet
name: load-agent-XXXXX
subsets:
- name: bandwidthPackage-1
maxReplicas: 300
patch:
metadata:
annotations:
k8s.aliyun.com/eip-common-bandwidth-package-id: <id1>

- ...

- name: bandwidthPackage-10
maxReplicas: 300
patch:
metadata:
annotations:
k8s.aliyun.com/eip-common-bandwidth-package-id: <id10>
- name: no-eip

Case Study 2: Compatibility for Scaling Managed K8S Cluster Services to Serverless Instances​

A company had a web service running on an IDC that needed to scale up due to business growth but could not expand the local data center. They chose to use virtual nodes to access cloud-based Serverless elastic compute power, forming a hybrid cloud. Their application used acceleration services like Fluid, which were pre-deployed on nodes in the IDC but not available in the serverless subset. Therefore, they needed to inject a sidecar into cloud Pods to provide acceleration capabilities.

To achieve this without modifying the existing Deployment's 8 replicas, they used WorkloadSpread to add a label to Pods scaled to each subset, which controlled the Fluid sidecar injection.

apiVersion: apps.kruise.io/v1alpha1
kind: WorkloadSpread
metadata:
name: data-processor-spread
spec:
targetRef:
apiVersion: apps/v1
kind: Deployment
name: data-processor
subsets:
- name: local
maxReplicas: 8
patch:
metadata:
labels:
serverless.fluid.io/inject: "false"
- name: aliyun-acs
patch:
metadata:
labels:
serverless.fluid.io/inject: "true"

UnitedDeployment: A Native Workload with Built-in Elasticity

UnitedDeployment is an advanced workload provided by the OpenKruise community that natively supports partition management. Unlike WorkloadSpread, which enhances basic workloads, UnitedDeployment offers a new mode for managing partitioned elastic applications. It defines applications through a single template, and the controller creates and manages multiple secondary workloads to match different subsets. UnitedDeployment manages the entire lifecycle of applications within a single resource, including definition, partitioning, scaling, and upgrades.

Example Configuration​

apiVersion: apps.kruise.io/v1alpha1
kind: UnitedDeployment
metadata:
name: sample-ud
spec:
replicas: 6
selector:
matchLabels:
app: sample
template:
cloneSetTemplate:
metadata:
labels:
app: sample
spec:
# CloneSet Spec
...
topology:
subsets:
- name: ecs
nodeSelectorTerm:
matchExpressions:
- key: node-type
operator: In
values:
- ecs
maxReplicas: 2
- name: acs-serverless
nodeSelectorTerm:
matchExpressions:
- key: node-type
operator: In
values:
- acs-virtual-kubelet

Advantages of UnitedDeployment​

All-In-One Elastic Application Management​

UnitedDeployment offers comprehensive all-in-one application management, enabling users to define applications, manage subsets, scale, and upgrade using a single resource.

The UnitedDeployment controller manages a corresponding type of secondary workload for each subset based on the workload template, without requiring additional attention from the user. Users only need to manage the application template and subsets; the UnitedDeployment controller will handle subsequent management tasks for each secondary workload, including creation, modification, and deletion. The controller also monitors the status of Pods created by these workloads when necessary to make corresponding adjustments.

It is the secondary workload controllers implement the specific scaling and updating operations. Thus, scaling and updating using UnitedDeployment produces exactly the same effect as directly using the corresponding workload. For example, a UnitedDeployment will inherit the same grayscale publishing and in-place upgrade capabilities from CloneSet when created with a CloneSet template.

Advanced Subset Management​

UnitedDeployment incorporates two capacity allocation algorithms, enabling users to handle various scenarios of elastic applications through detailed subset capacity configurations.

The elastic allocation algorithm implements a classic elastic capacity allocation method similar to WorkloadSpread: by setting upper and lower capacity limits for each subset, Pods are scaled up in the defined order of subsets and scaled down in reverse order. This method has been thoroughly introduced earlier, so it will not be elaborated further here.

The specified allocation algorithm represents a new approach to capacity allocation. It directly assigns fixed numbers or percentages to some subsets and reserves at least one elastic subset to distribute the remaining replicas.

In addition to capacity allocation, UnitedDeployment also allows customizing any Pod Spec fields (including container images) for each subset, which is similar to WorkloadSpread. This grants UnitedDeployment's subset configuration with powerful flexibility.

Adaptive Elasticity​

UnitedDeployment offers robust adaptive elasticity, automating scaling and rescheduling operations to reduce operational overhead. It supports Kubernetes Horizontal Pod Autoscaler (HPA), enabling automatic scaling based on predefined conditions while adhering strictly to subset configurations.

UnitedDeployment also offers adaptive Pod rescheduling capabilities similar to WorkloadSpread. Additionally, it allows configuration of timeout durations for scheduling failures and recovery times for subsets from unscheduable status, providing enhanced control over adaptive scheduling.

Limitations of UnitedDeployment​

The many advantages of UnitedDeployment stem from its all-in-one management capabilities as an independent workload. However, this also leads to the drawback of higher business transformation intrusiveness. For users' existing application, it is necessary to modify PaaS systems and tools (such as operation and maintenance systems, release systems, etc.) to switch from existing workloads like Deployment and CloneSet to UnitedDeployment.

Case Study 1: Elastic Scaling of Pods to Virtual Nodes with Adaptation for Serverless Containers​

Cloud providers typically offer three types of Kubernetes services:

  1. Managed clusters with fixed nodes using cloud servers purchased by users.
  2. Serverless clusters delivering container computing power directly via virtual node technology.
  3. Hybrid clusters containing both managed nodes and virtual nodes.

In this case, a company planned to launch a new service with significant peak-to-valley traffic differences (up to tenfold). To handle this characteristic, they purchased a batch of cloud servers to form a managed cluster nodepool for handling baseline traffic and intended to quickly scale out new replicas to a serverless subset during peak hours. Additionally, their application required extra configuration to run in the Serverless environment. Below is an example configuration:

apiVersion: apps.kruise.io/v1alpha1
kind: UnitedDeployment
metadata:
name: elastic-app
spec:
# Omitted business workload template
...
topology:
# Enable Adaptive scheduling to dispatch Pod replicas to ECS node pools and ACS instances adaptively
scheduleStrategy:
type: Adaptive
adaptive:
# Start scheduling to ACS Serverless instances 10 seconds after ECS node scheduling failure
rescheduleCriticalSeconds: 10
subsets:
# Prioritize ECS without an upper limit; only schedule to ACS when ECS fails
# During scale-in, delete ACS instances first, then ECS node pool Pods
- name: ecs
nodeSelectorTerm:
matchExpressions:
- key: type
operator: NotIn
values:
- acs-virtual-kubelet
- name: acs-serverless
nodeSelectorTerm:
matchExpressions:
- key: type
operator: In
values:
- acs-virtual-kubelet
# Use patch to modify environment variables for Pods scheduled to elastic computing power, enabling Serverless mode
patch:
spec:
containers:
- name: main
env:
- name: APP_RUNTIME_MODE
value: SERVERLESS
---
# Combine with HPA for automatic scaling
apiVersion: autoscaling/v2
kind: HorizontalPodAutoscaler
metadata:
name: elastic-app-hpa
spec:
minReplicas: 1
maxReplicas: 100
metrics:
- type: Resource
resource:
name: cpu
target:
type: Utilization
averageUtilization: 2
scaleTargetRef:
apiVersion: apps.kruise.io/v1alpha1
kind: UnitedDeployment
name: elastic-app

Case Study 2: Allocating Different Resources to Pods with Different CPU Types​

In this case, a company purchased several cloud server instances with Intel, AMD, and ARM platform CPUs to prepare for launching a new service. They wanted Pods scheduled on different platforms to exhibit similar performance. After stress testing, it was found that, compared to Intel CPUs as the benchmark, AMD platforms needed more CPU cores, while ARM platforms required more memory.

apiVersion: apps.kruise.io/v1alpha1
kind: UnitedDeployment
metadata:
name: my-app
spec:
replicas: 4
selector:
matchLabels:
app: my-app
template:
deploymentTemplate:
... # Omitted business workload template
topology:
# Intel, AMD, and Yitian 710 ARM machines carry 50%, 25%, and 25% of the replicas respectively
subsets:
- name: intel
replicas: 50%
nodeSelectorTerm:
... # Select Intel node pool through labels
patch:
spec:
containers:
- name: main
resources:
limits:
cpu: 2000m
memory: 4000Mi
- name: amd64
replicas: 25%
nodeSelectorTerm:
... # Select AMD node pool through labels
# Allocate more CPU to AMD platform
patch:
spec:
containers:
- name: main
resources:
limits:
cpu: 3000m
memory: 4000Mi
- name: yitian-arm
replicas: 25%
nodeSelectorTerm:
... # Select ARM node pool through labels
# Allocate more memory to ARM platform
patch:
spec:
containers:
- name: main
resources:
limits:
cpu: 2000m
memory: 6000Mi

Summary

Elastic computing power can significantly reduce business costs and effectively increase the performance ceiling of services. To make good use of elastic computing power, it is necessary to choose appropriate elastic components based on specific application characteristics. The following table summarizes the capabilities of the two components introduced in this article, hoping to provide some reference.

ComponentPartition PrincipleEase of ModificationGranularity of PartitionElasticity Capability
WorkloadSpreadModify Pods via WebhookHighMediumMedium
UnitedDeploymentCreate multiple workloads via templatesLowHighHigh

OpenKruise V1.4 Release, New Job Sidecar Terminator Capability

· 8 min read
Mingshan Zhao
Member of OpenKruise

OpenKruise (https://github.com/openkruise/kruise) is an open-source cloud-native application automation management suite. It is also a current incubating project hosted by the Cloud Native Computing Foundation (CNCF). It is a standard extension component based on Kubernetes that is widely used in production of internet scale company. It also closely follows upstream community standards and adapts to the technical improvement and best practices for internet-scale scenarios.

OpenKruise has released the latest version v1.4 on March 31, 2023 (ChangeLog), with the addition of the Job Sidecar Terminator feature. This article provides a comprehensive overview of the new version.

Upgrade Notice​

  • To facilitate the use of Kruise's enhanced capabilities, some stable capabilities have been enabled by default, including ResourcesDeletionProtection, WorkloadSpread, PodUnavailableBudgetDeleteGate, InPlaceUpdateEnvFromMetadata, StatefulSetAutoDeletePVC, and PodProbeMarkerGate. Most of these capabilities require special configuration to take effect, so enabling them by default generally has no impact on existing clusters. If you do not want to use some of these features, you can turn them off during the upgrade process.
  • The leader election method for Kruise-Manager has been migrated from configmaps to configmapsleases to prepare for future migration to the leases method. In addition, this is an officially provided smooth upgrade method that will not affect existing clusters.

2. New Job Sidecar Terminator Capability​

In Kubernetes, for Job workloads, it is commonly desired that when the main container completes its task and terminates, the Pod should enter a completed state. However, when these Pods have Long-Running Sidecar containers, the Sidecar container cannot terminate itself after the main container has exited, causing the Pod to remain in an incomplete state. The community's common solution to this problem usually involves modifying both the Main and Sidecar containers to use Volume sharing to achieve the effect of the Sidecar container exiting after the Main container has completed.

While the community's solution can solve this problem, it requires modification of the containers, especially for commonly used Sidecar containers, which incurs high costs for modification and maintenance.

To address this, we have added a controller called SidecarTerminator to Kruise. This controller is specifically designed to listen for completion status of the main container in this scenario and select an appropriate time to terminate the Sidecar container in the Pod, without requiring intrusive modification of the Main and Sidecar containers.

Pods on real nodes​

For pods running on regular nodes, it is very easy to use this feature since Kruise daemon can be installed. Users just need to add a special env to identify the target sidecar container in the pod, and the controller will use the ContainerRecreateRequest(CRR) capability provided by Kruise Daemon to terminate these sidecar containers at the appropriate time.

kind: Job
spec:
template:
spec:
containers:
- name: sidecar
env:
- name: KRUISE_TERMINATE_SIDECAR_WHEN_JOB_EXIT
value: "true"
- name: main
...

Pods on virtual nodes​

For some platforms that provide Serverless containers, such as ECI or Fargate, their pods can only run on virtual nodes such as Virtual-Kubelet. However, Kruise Daemon cannot be deployed and work on these virtual nodes, which makes it impossible to use the CRR capability to terminate containers.

Fortunately, we can use the Pod in-place upgrade mechanism provided by native Kubernetes to achieve the same goal: just construct a special image whose only purpose is to make the container exit quickly once started. In this way, when exiting the sidecar, just replace the original sidecar image with the fast exit image to achieve the purpose of exiting the sidecar.

Step 1: Prepare a fast exit image​

  • The image only needs to have a very simple logic: when the container of this image starts, it exits directly with an exit code of 0.
  • The image needs to be compatible with the commands and args of the original sidecar image to prevent errors when the container starts.

Step 2: Configure the special image in the Sidecar environment variable​

kind: Job
spec:
template:
spec:
containers:
- name: sidecar
env:
- name: KRUISE_TERMINATE_SIDECAR_WHEN_JOB_EXIT_WITH_IMAGE
value: "example/quick-exit:v1.0.0"
- name: main
...

Replace "example/quick-exit:v1.0.0" with the fast exit image that you have prepared in step 1.

Notice​

  • The sidecar container must be able to respond to the SIGTERM signal, and when it receives this signal, the entrypoint process needs to exit (that is, the sidecar container needs to exit), and the exit code should be 0.
  • This feature applies to any Pod managed by a Job type Workload, as long as their RestartPolicy is Never/OnFailure.
  • Containers with the environment variable KRUISE_TERMINATE_SIDECAR_WHEN_JOB_EXIT will be treated as sidecar containers, while other containers will be treated as main containers. The sidecar container will only be terminated after all main containers have completed:
    • Under the Never restart policy, once the main container exits, it will be considered "completed".
    • Under the OnFailure restart policy, the exit code of the main container must be 0 to be considered "completed".
  • In Pods on real nodes mode, KRUISE_TERMINATE_SIDECAR_WHEN_JOB_EXIT has a higher priority than KRUISE_TERMINATE_SIDECAR_WHEN_JOB_EXIT_WITH_IMAGE

Advanced Workload Improvement​

CloneSet Optimization Performance: New FeatureGate CloneSetEventHandlerOptimization​

Currently, whether it's a change in the state or metadata of a Pod,, the Pod Update event will trigger the CloneSet reconcile logic. CloneSet Reconcile is configured with three workers by default, which is not a problem for smaller cluster scenarios.

However, for larger or busy clusters, these unneccesary reconciles will block the true CloneSet reconcile and delay changes such as rolling updates of CloneSet. To solve this problem, you can turn on the feature-gate CloneSetEventHandlerOptimization to reduce some unnecessary enqueueing of reconciles.

CloneSet New disablePVCReuse Field​

If a Pod is directly deleted or evicted by other controller or user, the PVCs associated with the Pod still remain. When the CloneSet controller creates new Pods, it will reuse existing PVCs.

However, if the Node where the Pod is located experiences a failure, reusing existing PVCs may cause the new Pod to fail to start. For details, please refer to issue 1099. To solve this problem, you can set the disablePVCReuse=true field. After the Pod is evicted or deleted, the PVCs associated with the Pod will be automatically deleted and will no longer be reused.

apiVersion: apps.kruise.io/v1alpha1
kind: CloneSet
spec:
...
replicas: 4
scaleStrategy:
disablePVCReuse: true

CloneSet New PreNormal Lifecycle​

CloneSet currently supports two lifecycle hooks, PreparingUpdate and PreparingDelete, which are used for graceful application termination. For details, please refer to the Community Documentation. In order to support graceful application deployment, a new state called PreNormal has been added, as follows:

apiVersion: apps.kruise.io/v1alpha1
kind: CloneSet
spec:
# define with finalizer
lifecycle:
preNormal:
finalizersHandler:
- example.io/unready-blocker

# or define with label
# lifecycle:
# preNormal:
# labelsHandler:
# example.io/block-unready: "true"

When CloneSet creates a Pod (including normal scaling and upgrades):

  • The Pod will only be considered "Available" and enter the "Normal" state if it meets the definition of the PreNormal hook.

This is useful for some post-checks when creating Pods, such as checking if the Pod has been mounted to the SLB backend, so as to avoid traffic loss caused by new instance mounting failure after the old instance is destroyed during rolling upgrade.

4. Enhanced Operations Improvement​

ContainerRestart New forceRecreate Field​

When creating a CRR resource, if the container is in the process of starting up, the CRR will not restart the container again. If you want to force a container restart, you can enable the following field:

apiVersion: apps.kruise.io/v1alpha1
kind: ContainerRecreateRequest
spec:
...
strategy:
forceRecreate: true

ImagePullJob Support Attach metadata into cri interface​

When Kubelet creates a Pod, Kubelet will attach metadata to the container runtime using CRI interface. The image repository can use this metadata information to identify the business related to the starting container. Some container actions of low business value can be degraded to protect the overloaded repository.

OpenKruise's imagePullJob also supports similar capabilities, as follows:

apiVersion: apps.kruise.io/v1alpha1
kind: ImagePullJob
spec:
...
image: nginx:1.9.1
sandboxConfig:
annotations:
io.kubernetes.image.metrics.tags: "cluster=cn-shanghai"
labels:
io.kubernetes.image.app: "foo"

Get Involved​

Welcome to get involved with OpenKruise by joining us in Github/Slack/DingTalk/WeChat. Have something you’d like to broadcast to our community? Share your voice at our Bi-weekly community meeting (Chinese), or through the channels below:

  • Join the community on Slack (English).
  • Join the community on DingTalk: Search GroupID 23330762 (Chinese).
  • Join the community on WeChat (new): Search User openkruise and let the robot invite you (Chinese).

OpenKruise v1.3, New Custom Pod Probe Capabilities and Significant Performance Improvements for Large-Scale Clusters

· 10 min read
Mingshan Zhao
Member of OpenKruise

We’re pleased to announce the release of OpenKruise 1.3, which is a CNCF Sandbox level project.

OpenKruise is an extended component suite for Kubernetes, which mainly focuses on application automations, such as deployment, upgrade, ops and availability protection. Mostly features provided by OpenKruise are built primarily based on CRD extensions. They can work in pure Kubernetes clusters without any other dependences.

What's new?​

In release v1.3, OpenKruise provides a new CRD named PodProbeMarker, improves its performance in large-scale clusters, Advanced DaemonSet support pre-download image, and some new features have been added to CloneSet, WorkloadSpread, AdvancedCronJob, SidecarSet etc.

Here we are going to introduce some changes of it.

1. New CRD and Controller: PodProbeMarker​

Kubernetes provides three Pod lifecycle management:

  • Readiness Probe Used to determine whether the business container is ready to respond to user requests. If the probe fails, the Pod will be removed from Service Endpoints.
  • Liveness Probe Used to determine the health status of the container. If the probe fails, the kubelet will restart the container.
  • Startup Probe Used to know when a container application has started. If such a probe is configured, it disables liveness and readiness checks until it succeeds.

So the Probe capabilities provided in Kubernetes have defined specific semantics and related behaviors. In addition, there is actually a need to customize Probe semantics and related behaviors, such as:

  • GameServer defines Idle Probe to determine whether the Pod currently has a game match, if not, from the perspective of cost optimization, the Pod can be scaled down.
  • K8S Operator defines the main-secondary probe to determine the role of the current Pod (main or secondary). When upgrading, the secondary can be upgraded first, so as to achieve the behavior of selecting the main only once during the upgrade process, reducing the service interruption time during the upgrade process.

OpenKruise provides the ability to customize the Probe and return the result to the Pod Status, and the user can decide the follow-up behavior based on the probe result.

An object of PodProbeMarker may look like this:

apiVersion: apps.kruise.io/v1alpha1
kind: PodProbeMarker
metadata:
name: game-server-probe
namespace: ns
spec:
selector:
matchLabels:
app: game-server
probes:
- name: Idle
containerName: game-server
probe:
exec:
command:
- /home/game/idle.sh
initialDelaySeconds: 10
timeoutSeconds: 3
periodSeconds: 10
successThreshold: 1
failureThreshold: 3
markerPolicy:
- state: Succeeded
labels:
gameserver-idle: 'true'
annotations:
controller.kubernetes.io/pod-deletion-cost: '-10'
- state: Failed
labels:
gameserver-idle: 'false'
annotations:
controller.kubernetes.io/pod-deletion-cost: '10'
podConditionType: game.io/idle

PodProbeMarker results can be viewed at Pod Object:

apiVersion: v1
kind: Pod
metadata:
labels:
app: game-server
gameserver-idle: 'true'
annotations:
controller.kubernetes.io/pod-deletion-cost: '-10'
name: game-server-58cb9f5688-7sbd8
namespace: ns
spec:
...
status:
conditions:
# podConditionType
- type: game.io/idle
# Probe State 'Succeeded' indicates 'True', and 'Failed' indicates 'False'
status: "True"
lastProbeTime: "2022-09-09T07:13:04Z"
lastTransitionTime: "2022-09-09T07:13:04Z"
# If the probe fails to execute, the message is stderr
message: ""

2. Performance optimization: significant performance improvements for large-scale clusters​

  • #1026 The introduction of a delayed queueing mechanism significantly optimizes the CloneSet controller work queue buildup problem when kruise-manager is pulled up in large-scale application clusters, ideally reducing initialization time by more than 80%.
  • #1027 Optimize PodUnavailableBudget controller Event Handler logic to reduce the number of irrelevant Pods in the queue.
  • #1011 The caching mechanism optimizes the CPU and Memory consumption of Advanced DaemonSet's repetitive simulation of Pod scheduling computations in large-scale clusters.
  • #1015, #1068 Significantly reduce runtime memory consumption in large clusters. Complete the Disable DeepCopy feature started in v1.1, and reduce the conversion consumption of expressions type label selector.

3. SidecarSet support inject specific historical version​

SidecarSet will record historical revision of some fields such as containers, volumes, initContainers, imagePullSecrets and patchPodMetadata via ControllerRevision. Based on this feature, you can easily select a specific historical revision to inject when creating Pods, rather than always inject the latest revision of sidecar.

SidecarSet records ControllerRevision in the same namespace as Kruise Manager. You can execute kubectl get controllerrevisions -n kruise-system -l kruise.io/sidecarset-name=<your-sidecarset-name> to list the ControllerRevisions of your SidecarSet. Moreover, the ControllerRevision name of current SidecarSet revision is shown in status.latestRevision field, so you can record it very easily.

There are two configuration methods as follows:

select revision via ControllerRevision name​

apiVersion: apps.kruise.io/v1alpha1
kind: SidecarSet
metadata:
name: sidecarset
spec:
...
updateStrategy:
partition: 90%
injectionStrategy:
revision:
revisionName: <specific-controllerrevision-name>

select revision via custom version label​

You can add or update the label apps.kruise.io/sidecarset-custom-version=<your-version-id> to SidecarSet when creating or publishing SidecarSet, to mark each historical revision. SidecarSet will bring this label down to the corresponding ControllerRevision object, and you can easily use the <your-version-id> to describe which historical revision you want to inject.

Assume that you are publishing version-2 in canary way (you wish only 10% Pods will be upgraded), and you want to inject the stable version-1 to newly-created Pods to reduce the risk of the canary publishing:

apiVersion: apps.kruise.io/v1alpha1
kind: SidecarSet
metadata:
name: sidecarset
labels:
apps.kruise.io/sidecarset-custom-version: example/version-2
spec:
...
updateStrategy:
partition: 90%
injectionStrategy:
revision:
customVersion: example/version-1

4. SidecarSet support inject pod annotations​

SidecarSet support inject pod annotations, as follows:

apiVersion: apps.kruise.io/v1alpha1
kind: SidecarSet
spec:
containers:
...
patchPodMetadata:
- annotations:
oom-score: '{"log-agent": 1}'
custom.example.com/sidecar-configuration: '{"command": "/home/admin/bin/start.sh", "log-level": "3"}'
patchPolicy: MergePatchJson
- annotations:
apps.kruise.io/container-launch-priority: Ordered
patchPolicy: Overwrite | Retain

patchPolicy is the injected policy, as follows:

  • Retain: By default, if annotation[key]=value exists in the Pod, the original value of the Pod will be retained. Inject annotations[key]=value2 only if annotation[key] does not exist in the Pod.
  • Overwrite: Corresponding to Retain, when annotation[key]=value exists in the Pod, it will be overwritten value2.
  • MergePatchJson: Corresponding to Overwrite, the annotations value is a json string. If the annotations[key] does not exist in the Pod, it will be injected directly. If it exists, do a json value merge. For example: annotations[oom-score]='{"main": 2}' exists in the Pod, after injection, the value json is merged into annotations[oom-score]='{"log-agent": 1, "main": 2}'.

Note: When the patchPolicy is Overwrite and MergePatchJson, the annotations can be updated synchronously when the SidecarSet in-place update the Sidecar Container. However, if only the annotations are modified, it will not take effect. It must be in-place update together with the sidecar container image. When patchPolicy is Retain, the annotations will not be updated when the SidecarSet in-place update the Sidecar Container.

According to the above configuration, when the sidecarSet is injected into the sidecar container, it will inject Pod annotations synchronously, as follows:

apiVersion: v1
kind: Pod
metadata:
annotations:
apps.kruise.io/container-launch-priority: Ordered
oom-score: '{"log-agent": 1, "main": 2}'
custom.example.com/sidecar-configuration: '{"command": "/home/admin/bin/start.sh", "log-level": "3"}'
name: test-pod
spec:
containers:
...

Note: SidecarSet should not modify any configuration outside the sidecar container for security consideration, so if you want to use this capability, you need to first configure SidecarSet_PatchPodMetadata_WhiteList whitelist or turn off whitelist checks via Feature-gate SidecarSetPatchPodMetadataDefaultsAllowed=true.

5. Advanced DaemonSet support pre-downloading image for update​

If you have enabled the PreDownloadImageForDaemonSetUpdate feature-gate, DaemonSet controller will automatically pre-download the image you want to update to the nodes of all old Pods. It is quite useful to accelerate the progress of applications upgrade.

The parallelism of each new image pre-downloading by DaemonSet is 1, which means the image is downloaded on nodes one by one. You can change the parallelism using apps.kruise.io/image-predownload-parallelism annotation on DaemonSet according to the capability of image registry, for registries with more bandwidth and P2P image downloading ability, a larger parallelism can speed up the pre-download process.

apiVersion: apps.kruise.io/v1alpha1
kind: DaemonSet
metadata:
annotations:
apps.kruise.io/image-predownload-parallelism: "10"

6. CloneSet Scaling with PreparingDelete​

CloneSet considers Pods in PreparingDelete state as normal by default, which means these Pods will still be calculated in the replicas number.

In this situation:

  • if you scale down replicas from N to N-1, when the Pod to be deleted is still in PreparingDelete, you scale up replicas to N, the CloneSet will move the Pod back to Normal.
  • if you scale down replicas from N to N-1 and put a Pod into podsToDelete, when the specific Pod is still in PreparingDelete, you scale up replicas to N, the CloneSet will not create a new Pod until the specific Pod goes into terminating.
  • if you specifically delete a Pod without replicas changed, when the specific Pod is still in PreparingDelete, the CloneSet will not create a new Pod until the specific Pod goes into terminating.

Since Kruise v1.3.0, you can put a apps.kruise.io/cloneset-scaling-exclude-preparing-delete: "true" label into CloneSet, which indicates Pods in PreparingDelete will not be calculated in the replicas number.

In this situation:

  • if you scale down replicas from N to N-1, when the Pod to be deleted is still in PreparingDelete, you scale up replicas to N, the CloneSet will move the Pod back to Normal.
  • if you scale down replicas from N to N-1 and put a Pod into podsToDelete, even if the specific Pod is still in PreparingDelete, you scale up replicas to N, the CloneSet will create a new Pod immediately.
  • if you specifically delete a Pod without replicas changed, even if the specific Pod is still in PreparingDelete, the CloneSet will create a new Pod immediately.

7. Advanced CronJob Time zones​

All CronJob schedule: times are based on the timezone of the kruise-controller-manager by default, which means the timezone set for the kruise-controller-manager container determines the timezone that the cron job controller uses.

However, we have introduce a spec.timeZone field in v1.3.0. You can set it to the name of a valid time zone name. For example, setting spec.timeZone: "Etc/UTC" instructs Kruise to interpret the schedule relative to Coordinated Universal Time.

A time zone database from the Go standard library is included in the binaries and used as a fallback in case an external database is not available on the system.

8. Other changes​

For more changes, their authors and commits, you can read the Github release.

Get Involved​

Welcome to get involved with OpenKruise by joining us in Github/Slack/DingTalk/WeChat. Have something you’d like to broadcast to our community? Share your voice at our Bi-weekly community meeting (Chinese), or through the channels below:

  • Join the community on Slack (English).
  • Join the community on DingTalk: Search GroupID 23330762 (Chinese).
  • Join the community on WeChat (new): Search User openkruise and let the robot invite you (Chinese).

OpenKruise v1.2, new PersistentPodState feature to achieve IP retention

· 8 min read
Siyu Wang
Maintainer of OpenKruise

We’re pleased to announce the release of OpenKruise 1.2, which is a CNCF Sandbox level project.

OpenKruise is an extended component suite for Kubernetes, which mainly focuses on application automations, such as deployment, upgrade, ops and availability protection. Mostly features provided by OpenKruise are built primarily based on CRD extensions. They can work in pure Kubernetes clusters without any other dependences.

What's new?​

In release v1.2, OpenKruise provides a new CRD named PersistentPodState, some new fields of CloneSet status and lifecycle hook, and optimization of PodUnavailableBudget.

Here we are going to introduce some changes of it.

1. New CRD and Controller: PersistentPodState​

With the development of cloud native, more and more companies start to deploy stateful services (e.g., Etcd, MQ) using Kubernetes. K8S StatefulSet is a workload for managing stateful services, and it considers the deployment characteristics of stateful services in many aspects. However, StatefulSet persists only limited pod state, such as Pod Name is ordered and unchanging, PVC persistence, and cannot cover other states, e.g. Pod IP retention, priority scheduling to previously deployed Nodes, etc. Typical Cases:

  • Service Discovery Middleware services are exceptionally sensitive to the Pod IP after deployment, requiring that the IP cannot be changed.

  • Database services persist data to the host disk, and changes to the Node to which they belong will result in data loss.

In response to the above description, by customizing PersistentPodState CRD, Kruise is able to persistent other states of the Pod, such as "IP Retention".

An object of PersistentPodState may look like this:

apiVersion: apps.kruise.io/v1alpha1
kind: PersistentPodState
metadata:
name: echoserver
namespace: echoserver
spec:
targetRef:
# Native k8s or kruise StatefulSet
# only support StatefulSet
apiVersion: apps.kruise.io/v1beta1
kind: StatefulSet
name: echoserver
# required node affinity. As follows, Pod rebuild will force deployment to the same zone
requiredPersistentTopology:
nodeTopologyKeys:
- failure-domain.beta.kubernetes.io/zone[,other node labels]
# preferred node affinity. As follows, Pod rebuild will preferred deployment to the same node
preferredPersistentTopology:
- preference:
nodeTopologyKeys:
- kubernetes.io/hostname[,other node labels]
# int [1, 100]
weight: 100

"IP Retention" should be a common requirement for K8S deployments of stateful services. It does not mean "Specified Pod IP", but requires that the Pod IP does not change after the first deployment, either by service release or by machine eviction. To achieve this, we need the K8S network component to support Pod IP retention and the ability to keep the IP as unchanged as possible. In this article, we have modified the Host-local plugin in the flannel network component so that it can achieve the effect of keeping the Pod IP unchanged under the same Node. Related principles will not be stated here, please refer to the code: host-local.

IP retention seems to be supported by the network component, how is it related with PersistentPodState? Well, there are some limitations to the implementation of "Pod IP unchanged" by network components. For example, flannel can only support the same Node to keep the Pod IP unchanged. However, the most important feature of K8S scheduling is "uncertainty", so "how to ensure that Pods are rebuilt and scheduled to the same Node" is the problem that PersistentPodState solves.

Also you can add the annotations below on your StatefulSet or Advanced StatefulSet, to let Kruise automatically create a PersistentPodState object for the StatefulSet. So you don't have to create it manually.

apiVersion: apps.kruise.io/v1alpha1
kind: StatefulSet
metadata:
annotations:
# auto generate PersistentPodState
kruise.io/auto-generate-persistent-pod-state: "true"
# preferred node affinity, As follows, Pod rebuild will preferred deployment to the same node
kruise.io/preferred-persistent-topology: kubernetes.io/hostname[,other node labels]
# required node affinity, As follows, Pod rebuild will force deployment to the same zone
kruise.io/required-persistent-topology: failure-domain.beta.kubernetes.io/zone[,other node labels]

2. CloneSet percentage partition calculation changed (breaking), and a new field in its status​

Previously, CloneSet calculates its partition with round up if it is a percentage value, which means even you set partition to be a percentage less than 100%, it might update no Pods to the new revision. For example, the real partition of a CloneSet with replicas=8 and partition=90% will be calculated as 8 because of 8 * 90% with round up, so it will not update any Pod. This is a little confused, especially when we are using a rollout component like Kruise Rollout or Argo.

So since v1.2, CloneSet will make sure there is at lease one Pod should be updated when partition is a percentage less than 100%, unless the CloneSet has replicas <= 1.

However, it might be difficult for users to understand this arithmetic, but they have to known the expected updated number of Pods after a percentage partition was set.

So we also provide a new field expectedUpdatedReplicas in CloneSet status, which directly shows the expected updated number of Pods based on the given partition. Users only have to compare status.updatedReplicas >= status.expectedUpdatedReplicas to decide whether their CloneSet has finished rolling out new revision under partition restriction or not.

apiVersion: apps.kruise.io/v1alpha1
kind: CloneSet
spec:
replicas: 8
updateStrategy:
partition: 90%
status:
replicas: 8
expectedUpdatedReplicas: 1
updatedReplicas: 1
updatedReadyReplicas: 1

3. Able to mark Pod not-ready for lifecycle hook​

Kruise has already provided lifecycle hook in previous versions. CloneSet and Advanced StatefulSet support both PreDelete and InPlaceUpdate hooks, while Advanced DaemonSet only supports PreDelete hook.

Previously, the hooks only pause the operation and allow users to do something (for example remove pod from service endpoints) during Pod deleting and before/after in-place update. But the Pod is probably Ready during the hook state, so that removing it from some custom service implementation may break the rule of Kubernetes that we'd better only remove NotReady Pods from the endpoints.

So that a new field has been added into the lifecycle hook, markPodNotReady indicates the hooked Pod should be marked as NotReady or not.

type LifecycleStateType string

// Lifecycle contains the hooks for Pod lifecycle.
type Lifecycle struct
// PreDelete is the hook before Pod to be deleted.
PreDelete *LifecycleHook `json:"preDelete,omitempty"`
// InPlaceUpdate is the hook before Pod to update and after Pod has been updated.
InPlaceUpdate *LifecycleHook `json:"inPlaceUpdate,omitempty"`
}

type LifecycleHook struct {
LabelsHandler map[string]string `json:"labelsHandler,omitempty"`
FinalizersHandler []string `json:"finalizersHandler,omitempty"`

/********************** FEATURE STATE: 1.2.0 ************************/
// MarkPodNotReady = true means:
// - Pod will be set to 'NotReady' at preparingDelete/preparingUpdate state.
// - Pod will be restored to 'Ready' at Updated state if it was set to 'NotReady' at preparingUpdate state.
// Default to false.
MarkPodNotReady bool `json:"markPodNotReady,omitempty"`
/*********************************************************************/
}

For PreDelete hook, it will set Pod to be NotReady during PreparingDelete state if markPodNotReady is true, and the Pod can not be changed back to normal even if the replicas is increased again.

For InPlaceUpdate hook, it will set Pod to be NotReady during PreparingUpdate state if markPodNotReady is true, and the NotReady condition will be removed during Updated state.

4. PodUnavailableBudget supports any custom workloads and performance optimization​

Kubernetes offers PodDisruptionBudget to help users run highly available applications even when you introduce frequent voluntary disruptions, but it can only constrain the voluntary disruption triggered by the Eviction API.

In voluntary disruption scenarios, PodUnavailableBudget can achieve the effect of preventing application disruption or SLA degradation, which greatly improves the high availability of application services. It can not only protect application Pods from eviction but also deletion, in-place update and other operations that could make Pods not ready.

Previously, PodUnavailableBudget only supports some specific workloads like CloneSet and Deployment. But it can not recognize unknown workloads that may be defined by users themself.

Since v1.2 release, PodUnavailableBudget has supported any custom workloads to protect their Pods from unavailable operations. All you have to do is to declare scale subresource for those custom workloads.

It looks like this in CRD:

    subresources:
scale:
labelSelectorPath: .status.labelSelector
specReplicasPath: .spec.replicas
statusReplicasPath: .status.replicas

But if you are using kubebuilder or operator-sdk to generate your project, one line comment on your workload struct will be fine:

// +kubebuilder:subresource:scale:specpath=.spec.replicas,statuspath=.status.replicas,selectorpath=.status.labelSelector

Besides, PodUnavailableBudget also optimizes its performance for large-scale clusters by disable DeepCopy from client list.

5. Other changes​

For more changes, their authors and commits, you can read the Github release.

Get Involved​

Welcome to get involved with OpenKruise by joining us in Github/Slack/DingTalk/WeChat. Have something you’d like to broadcast to our community? Share your voice at our Bi-weekly community meeting (Chinese), or through the channels below:

  • Join the community on Slack (English).
  • Join the community on DingTalk: Search GroupID 23330762 (Chinese).
  • Join the community on WeChat (new): Search User openkruise and let the robot invite you (Chinese).

OpenKruise v1.1, features enhanced, improve performance in large-scale clusters

· 9 min read
Siyu Wang
Maintainer of OpenKruise

We’re pleased to announce the release of OpenKruise 1.1, which is a CNCF Sandbox level project.

OpenKruise is an extended component suite for Kubernetes, which mainly focuses on application automations, such as deployment, upgrade, ops and availability protection. Mostly features provided by OpenKruise are built primarily based on CRD extensions. They can work in pure Kubernetes clusters without any other dependences.

What's new?​

In release v1.1, OpenKruise optimizes some existing features, and improves its performance in large-scale clusters. Here we are going to introduce some changes of it.

Note that OpenKruise v1.1 bumps Kubernetes dependencies to v1.22, which means we can use new fields of up to K8s v1.22 in Pod template of workloads like CloneSet and Advanced StatefulSet. But OpenKruise can still be used in Kubernetes cluster >= 1.16 version.

1. Keep containers order for in-place update​

In the release v1.0 we published last year, OpenKruise has intruduced Container Launch Priority, which supports to define different priorities for containers in a Pod and keeps their start order during Pod creation.

But in v1.0, it can only control the order in Pod creation. If you try to update the containers in-place, they will be updated at the same time.

Recently, the community has discussed with some companies such as LinkedIn and get more input from the users. In some scenarios, the containers in Pod may have special relationship, for example base-container should firstly update its configuration before app-container update, or we have to forbid multiple containers updating together to avoid log-container losing the logs of app-container.

So, OpenKruise supports in-place update with container priorities since v1.1.

There is no extra options, just make sure containers have their launch priorities since Pod creation. If you modify them both in once in-place update, Kruise will firstly update the containers with higher priority. Then Kruise will not update the containers with lower priority util the higher one has updated successfully.

The in-place udpate here includes both modification of image and env from metadata, read the concept doc for more details

  • For pods without container launch priorities, no guarantees of the execution order during in-place update multiple containers.
  • For pods with container launch priorities:
    • keep execution order during in-place update multiple containers with different priorities.
    • no guarantees of the execution order during in-place update multiple containers with the same priority.

For example, we have the CloneSet that includes two containers with different priorities:

apiVersion: apps.kruise.io/v1alpha1
kind: CloneSet
metadata:
...
spec:
replicas: 1
template:
metadata:
annotations:
app-config: "... config v1 ..."
spec:
containers:
- name: sidecar
env:
- name: KRUISE_CONTAINER_PRIORITY
value: "10"
- name: APP_CONFIG
valueFrom:
fieldRef:
fieldPath: metadata.annotations['app-config']
- name: main
image: main-image:v1
updateStrategy:
type: InPlaceIfPossible

When we update the CloneSet to change app-config annotation and image of main container, which means both sidecar and main containers need to update, Kruise will firstly in-place update pods that recreates sidecar container with the new env from annotation.

At this moment, we can find the apps.kruise.io/inplace-update-state annotation in updated Pod and see its value:

{
"revision": "{CLONESET_NAME}-{HASH}", // the target revision name of this in-place update
"updateTimestamp": "2022-03-22T09:06:55Z", // the start time of this whole update
"nextContainerImages": {"main": "main-image:v2"}, // the next containers that should update images
// "nextContainerRefMetadata": {...}, // the next containers that should update env from annotations/labels
"preCheckBeforeNext": {"containersRequiredReady": ["sidecar"]}, // the pre-check must be satisfied before the next containers can update
"containerBatchesRecord":[
{"timestamp":"2022-03-22T09:06:55Z","containers":["sidecar"]} // the first batch of containers that have updated (it just means the spec of containers has updated, such as images in pod.spec.container or annotations/labels, but doesn't mean the real containers on node have been updated completely)
]
}

When the sidecar container has been updated successfully, Kruise will update the next main container. Finally, you will find the apps.kruise.io/inplace-update-state annotation looks like:

{
"revision": "{CLONESET_NAME}-{HASH}",
"updateTimestamp": "2022-03-22T09:06:55Z",
"lastContainerStatuses":{"main":{"imageID":"THE IMAGE ID OF OLD MAIN CONTAINER"}},
"containerBatchesRecord":[
{"timestamp":"2022-03-22T09:06:55Z","containers":["sidecar"]},
{"timestamp":"2022-03-22T09:07:20Z","containers":["main"]}
]
}

Usually, users only have to care about the containerBatchesRecord to make sure the containers are updated in different batches. If the Pod is blocking during in-place update, you should check the nextContainerImages/nextContainerRefMetadata and see if the previous containers in preCheckBeforeNext have been updated successfully and ready.

2. StatefulSetAutoDeletePVC​

Since Kubernetes v1.23, the upstream StatefulSet has supported StatefulSetAutoDeletePVC feature, it controls if and how PVCs are deleted during the lifecycle of a StatefulSet, refer to this doc.

So, Advanced StatefulSet has rebased this feature from upstream, which also requires you to enable StatefulSetAutoDeletePVC feature-gate during install/upgrade Kruise.

apiVersion: apps.kruise.io/v1beta1
kind: StatefulSet
spec:
...
persistentVolumeClaimRetentionPolicy: # optional
whenDeleted: Retain | Delete
whenScaled: Retain | Delete

Once enabled, there are two policies you can configure for each StatefulSet:

  • whenDeleted: configures the volume retention behavior that applies when the StatefulSet is deleted.
  • whenScaled: configures the volume retention behavior that applies when the replica count of the StatefulSet is reduced; for example, when scaling down the set.

For each policy that you can configure, you can set the value to either Delete or Retain.

  • Retain (default): PVCs from the volumeClaimTemplate are not affected when their Pod is deleted. This is the behavior before this new feature.
  • Delete: The PVCs created from the volumeClaimTemplate are deleted for each Pod affected by the policy. With the whenDeleted policy all PVCs from the volumeClaimTemplate are deleted after their Pods have been deleted. With the whenScaled policy, only PVCs corresponding to Pod replicas being scaled down are deleted, after their Pods have been deleted.

Note that:

  1. StatefulSetAutoDeletePVC only deletes PVCs created by volumeClaimTemplate instead of the PVCs created by user or related to StatefulSet Pod.
  2. The policies only apply when Pods are being removed due to the StatefulSet being deleted or scaled down. For example, if a Pod associated with a StatefulSet fails due to node failure, and the control plane creates a replacement Pod, the StatefulSet retains the existing PVC. The existing volume is unaffected, and the cluster will attach it to the node where the new Pod is about to launch.

3. Advanced DaemonSet refactor, lifecycle hook​

The behavior of Advanced DaemonSet used to be a little different with the upstream controller, such as it required extra configuration to choose whether not-ready and unschedulable nodes should be handled, which makes users confused and hard to understand.

In release v1.1, we have refactored Advanced DaemonSet to make it rebase with upstream. Now, the default behavior of Advanced DaemonSet should be the same as the upstream DaemonSet, which means users can conveniently modify the apiVersion field to convert a built-in DaemonSet to Advanced DaemonSet.

Meanwhile, we also add lifecycle hook for Advanced DaemonSet. Currently it supports preDelete hook, which allows users to do something (for example check node resources) before Pod deleting.

apiVersion: apps.kruise.io/v1alpha1
kind: DaemonSet
spec:
...
# define with label
lifecycle:
preDelete:
labelsHandler:
example.io/block-deleting: "true"

When Advanced DaemonSet delete a Pod (including scale in and recreate update):

  • Delete it directly if no lifecycle hook definition or Pod not matched preDelete hook
  • Otherwise, Advanced DaemonSet will firstly update Pod to PreparingDelete state and wait for user controller to remove the label/finalizer and Pod not matched preDelete hook

4. Improve performance by disable DeepCopy​

By default, when we are writing Operator/Controller with controller-runtime and use the Client interface in sigs.k8s.io/controller-runtime/pkg/client to get/list typed objects, it will always get objects from Informer. That's known by most people.

But what's many people don't know, is that controller-runtime will firstly deep copy all the objects got from Informer and then return the copied objects.

This design aims to avoid developers directly modifying the objects in Informer. After DeepCopy, no matter how developers modify the objected returned by get/list, it will not change the objects in Informer, which are only synced by ListWatch from kube-apiserver.

However, in some large-scale clusters, mutliple controllers of OpenKruise and their workers are reconciling together, which may bring so many DeepCopy operations. For example, there are a lot of application CloneSets and some of them have managed thousands of Pods, then each worker will list all Pod of the CloneSet during Reconcile and there exists multiple workers. It brings CPU and Memory pressure to kruise-manager and even sometimes makes it Out-Of-Memory.

So I have submitted and merged DisableDeepCopy feature in upstream, which contains in controller-runtime >= v0.10 version. It allows developers to specify some resource types that will directly return the objects from Informer without DeepCopy during get/list.

For example, we can add cache options when initialize Manager in main.go to avoid DeepCopy for Pod objects.

    mgr, err := ctrl.NewManager(cfg, ctrl.Options{
...
NewCache: cache.BuilderWithOptions(cache.Options{
UnsafeDisableDeepCopyByObject: map[client.Object]bool{
&v1.Pod{}: true,
},
}),
})

But in Kruise v1.1, we re-implement Delegating Client instead of using the feature of controller-runtime. It allows developers to avoid DeepCopy with DisableDeepCopy ListOption in any list places, which is more flexible.

    if err := r.List(context.TODO(), &podList, client.InNamespace("default"), utilclient.DisableDeepCopy); err != nil {
return nil, nil, err
}

5. Other changes​

For more changes, their authors and commits, you can read the Github release.

Get Involved​

Welcome to get involved with OpenKruise by joining us in Github/Slack/DingTalk/WeChat. Have something you’d like to broadcast to our community? Share your voice at our Bi-weekly community meeting (Chinese), or through the channels below:

  • Join the community on Slack (English).
  • Join the community on DingTalk: Search GroupID 23330762 (Chinese).
  • Join the community on WeChat (new): Search User openkruise and let the robot invite you (Chinese).

OpenKruise v1.0, Reaching New Peaks of application automation

· 7 min read
Siyu Wang
Maintainer of OpenKruise

We’re pleased to announce the release of OpenKruise 1.0, which is a CNCF Sandbox level project.

OpenKruise is an extended component suite for Kubernetes, which mainly focuses on application automations, such as deployment, upgrade, ops and availability protection. Mostly features provided by OpenKruise are built primarily based on CRD extensions. They can work in pure Kubernetes clusters without any other dependences.

openkruise-features|center|450x400

Overall, OpenKruise currently provides features in these areas:

  • Application workloads: Enhanced strategies of deploy and upgrade for stateless/stateful/daemon applications, such as in-place update, canary/flowing upgrade.
  • Sidecar container management: supports to define sidecar container alone, which means it can inject sidecar containers, upgrade them with no effect on application containers and even hot upgrade.
  • Enhanced operations: such as restart containers in-place, pre-download images on specific nodes, keep containers launch priority in a Pod, distribute one resource to multiple namespaces.
  • Application availability protection: protect availability for applications that deployed in Kubernetes.

What's new?​

1. InPlace Update for environments​

Author: @FillZpp

OpenKruise has supported InPlace Update since very early version, mostly for workloads like CloneSet and Advanced StatefulSet. Comparing to recreate Pods during upgrade, in-place update only has to modify the fields in existing Pods.

inplace-update-comparation|center|450x400

As the picture shows above, we only modify the image field in Pod during in-place update. So that:

  • Avoid additional cost of scheduling, allocating IP, allocating and mounting volumes.
  • Faster image pulling, because we can reuse most of image layers pulled by the old image and only to pull several new layers.
  • When a container is in-place updating, the other containers in Pod will not be affected and remain running.

However, OpenKruise only supports to in-place update image field in Pod and has to recreate Pods if other fields need to update. All the way through, more and more users hope OpenKruise could support in-place update more fields such as env -- which is hard to implement, for it is limited by kube-apiserver.

After our unremitting efforts, OpenKruise finally support in-place update environments via Downward API since version v1.0. Take the CloneSet YAML below as an example, user has to set the configuration in annotation and write a env from it. After that, he just needs to modify the annotation value when changing the configuration. Kruise will restart all containers with env from the annotation in such Pod to enable the new configuration.

apiVersion: apps.kruise.io/v1alpha1
kind: CloneSet
metadata:
...
spec:
replicas: 1
template:
metadata:
annotations:
app-config: "... the real env value ..."
spec:
containers:
- name: app
env:
- name: APP_CONFIG
valueFrom:
fieldRef:
fieldPath: metadata.annotations['app-config']
updateStrategy:
type: InPlaceIfPossible

At the same time, we have removed the limit of imageID for in-place update, which means you can update a new image with the same imageID to the old image.

For more details please read documentation.

2. Distribute resources over multiple namespaces​

Author: @veophi

For the scenario, where the namespace-scoped resources such as Secret and ConfigMap need to be distributed or synchronized to different namespaces, the native k8s currently only supports manual distribution and synchronization by users one-by-one, which is very inconvenient.

Typical examples:

  • When users want to use the imagePullSecrets capability of SidecarSet, they must repeatedly create corresponding Secrets in relevant namespaces, and ensure the correctness and consistency of these Secret configurations;
  • When users want to configure some common environment variables, they probably need to distribute ConfigMaps to multiple namespaces, and the subsequent modifications of these ConfigMaps might require synchronization among these namespaces.

Therefore, in the face of these scenarios that require the resource distribution and continuously synchronization across namespaces, we provide a tool, namely ResourceDistribution, to do this automatically.

Currently, ResourceDistribution supports the two kind resources --- Secret & ConfigMap.

apiVersion: apps.kruise.io/v1alpha1
kind: ResourceDistribution
metadata:
name: sample
spec:
resource:
apiVersion: v1
kind: ConfigMap
metadata:
name: game-demo
data:
...
targets:
namespaceLabelSelector:
...
# or includedNamespaces, excludedNamespaces

So you can see ResourceDistribution is a kind of cluster-scoped CRD, which is mainly composed of two fields: resource and targets.

  • resource is a complete and correct resource structure in YAML style.
  • targets indicates the target namespaces that the resource should be distributed into.

For more details please read documentation.

3. Container launch priority​

Author: @Concurrensee

Containers in the same Pod might have dependencies, which means the application in one container runs depending on another container. For example:

  1. Container A has to start first. Container B can start only if A is already running.
  2. Container B has to exit first. Container A can stop only if B has already exited.

Currently, the sequences of containers start and stop are controlled by Kubelet. Kubernetes used to have a KEP, which plans to add a type field for container to identify the priority of start and stop. However, it has been refused because of sig-node thought it may bring a huge change to code.

So OpenKruise provides a feature named Container Launch Priority, which helps user control the sequence of containers start in a Pod.

  1. User only has to put the annotation apps.kruise.io/container-launch-priority: Ordered in a Pod, then Kruise will ensure all containers in this Pod should be started by the sequence of pod.spec.containers list.
  2. If you want to customize the launch sequence, you can add KRUISE_CONTAINER_PRIORITY environment in container. The range of the value is [-2147483647, 2147483647]. The container with higher priority will be guaranteed to start before the others with lower priority.

For more details please read documentation.

4. kubectl-kruise commandline tool​

Author: @hantmac

OpenKruise used to provide SDK like kruise-api and client-java for some programming languages, which can be imported into users' projects. On the other hand, some users also need to operate the workload resources with commandline in test environment.

However, the rollout, set image commands in original kubectl can only work for built-in workloads, such as Deployment and StatefulSet.

So, OpenKruise now provide a commandline tool named kubectl-kruise, which is a standard plugin of kubectl and can work for OpenKruise workload types.

# rollout undo cloneset
$ kubectl kruise rollout undo cloneset/nginx

# rollout status advanced statefulset
$ kubectl kruise rollout status statefulsets.apps.kruise.io/sts-demo

# set image of a cloneset
$ kubectl kruise set image cloneset/nginx busybox=busybox nginx=nginx:1.9.1

For more details please read documentation.

5. Other changes​

CloneSet:

  • Add maxUnavailable field in scaleStrategy to support rate limiting of scaling up.
  • Mark revision stable when all pods updated to it, won't wait all pods to be ready.

WorkloadSpread:

  • Manage the pods that have created before WorkloadSpread.
  • Optimize the update and retry logic for webhook injection.

Advanced DaemonSet:

  • Support in-place update Daemon Pod.
  • Support progressive annotation to control if pods creation should be limited by partition.

SidecarSet:

  • Fix SidecarSet filter active pods.
  • Add SourceContainerNameFrom and EnvNames fields in transferenv to make the container name flexible and the list shorter.

PodUnavailableBudget:

  • Add no pub-protection annotation to skip validation for the specific Pod.
  • PodUnavailableBudget controller watches workload replicas changed.

NodeImage:

  • Add --nodeimage-creation-delay flag to delay NodeImage creation after Node ready.

UnitedDeployment:

  • Fix pod NodeSelectorTerms length 0 when UnitedDeployment NodeSelectorTerms is nil.

Other optimization:

  • kruise-daemon list and watch pods using protobuf.
  • Export cache resync args and defaults to be 0 in chart value.
  • Fix http checker reloading after webhook certs updated.
  • Generate CRDs with original controller-tools and markers.

Get Involved​

Welcome to get involved with OpenKruise by joining us in Github/Slack/DingTalk/WeChat. Have something you’d like to broadcast to our community? Share your voice at our Bi-weekly community meeting (Chinese), or through the channels below:

  • Join the community on Slack (English).
  • Join the community on DingTalk: Search GroupID 23330762 (Chinese).
  • Join the community on WeChat: Search User openkruise and let the robot invite you (Chinese).

WorkloadSpread - Interpretation for OpenKruise v0.10.0 new feature

· 13 min read
GuangLei Cao
Contributor of OpenKruise
Weixiang Sun
Member of OpenKruise

Background​

Deploying an application in different zones, different hardware types, and even different clusters and cloud vendors is becoming a very common requirement with the development of cloud native techniques. For examples, these are some cases:

  1. Cases about disaster tolerant:
  • Application pods is scattered according to the nodes to avoid stacking.
  • Application pods is scattered according to available zones.
  • Different nodes/zones/domains require different scale of pods.
  1. Cases about cost control:
  • People deploy an applications preferentially to their own resource pool, and then deployed to elastic resource pool, such as ECI on Aliyun and Fragate on AWS, when own resources are insufficient. When shrinking, the elastic node is preferred to shrink to save cost.

In most cases, people always split their application into multiple workloads (such as several Deployment) to deploy. However,this solution often requires manual management by SRE team, or a deeply customized PAAS to support the careful management of multiple workloads for this one application.

In order to solve this problem, WorkloadSpread feature has been proposed in version v0.10.0 OpenKruise. It can support multi-kind of workloads, such as Deployment, Replicaset, Job, and Cloneset, to manage the partition deployment or elastic scaling. The application scenario and implementation principle of WorkloadSpread will be introduced in detail below to help users better understand this feature.


Introduction​

More details about WorkloadSpread can be found in Official Document.

In short, WorkloadSpread can distribute pods of a workload to different types of nodes according to certain rules, so as to meet the above fragmentation and elasticity scenarios. WorkloadSpread is non-invasive, "plug and play", and can be effective for stock workloads.


Let's make a simple comparison with some related works in the community.

「1」Pod Topology Spread Constrains​

Pod topology spread constraints is a solution provided by Kubernetes community. It can horizontally scatter pods according to topology key. The scheduler will select the node that matches the conditions according to the configuration if users defined this rule.

Since Pod Topology Spread is evenly dispersed, it cannot support exact customized partition number and proportion configuration. Furthermore, the distribution of pods will be destroyed when scaling down. Using WorkloadSpread can avoid these problems.

「2」UnitedDeploymen​

UnitedDeployment is a solution provided by the OpenKruise community. It can manage pods in multiple regions by creating and managing multiple workloads.

UnitedDeployment supports the requirements of fragmentation and flexibility very well. But, it is a new workload, and the use cost and migration costs will be relatively high, whereas WorkloadSpread is a lightweight solution, which only needs to apply a simple configuration to associate the workload.


Use Case​

In the section, I will list some application scenarios of WorkloadSpread and give corresponding configurations to help users quickly understand the WorkloadSpread feature.

「1」Deploy 100 pods to normal node pool, rest pods to elastic node pool​

case-1

subsets:
- name: subset-normal
maxReplicas: 100
requiredNodeSelectorTerm:
matchExpressions:
- key: app.deploy/zone
operator: In
values:
- normal
- name: subset-elastic
# maxReplicas==nil means no limit for replicas
requiredNodeSelectorTerm:
matchExpressions:
- key: app.deploy/zone
operator: In
values:
- elastic

When the workload has less than 100 replicas, all pods will be deployed to the normal node pool, and more than 100 are deployed to the elastic node pool. When scaling down, the pods on the elastic node will be deleted first.

Since workload spread limits the distribution of workload, but does not invade workload. Users can also dynamically adjust the number of replicas according to the resource load in combination with HPA.

In this way, it will be automatically scheduled to the elastic node pool when receiving peak flow, and give priority to releasing the resources in the elastic resource pool when the peak gone.

「1」Deploy pods to normal node pool first, to elastic resource pool when normal node pool is insufficient​

case-2

scheduleStrategy:
type: Adaptive
adaptive:
rescheduleCriticalSeconds: 30
disableSimulationSchedule: false
subsets:
- name: subset-normal
requiredNodeSelectorTerm:
matchExpressions:
- key: app.deploy/zone
operator: In
values:
- normal
- name: subset-elastic
requiredNodeSelectorTerm:
matchExpressions:
- key: app.deploy/zone
operator: In
values:
- elastic

Both subsets have no limit on the number of replicas, and the Adaptive rescheduling policy are enabled. The goal is to preferentially deploy to the normal node pool. When normal resources are insufficient, webhook will select elastic nodes through simulated scheduling. When the pod in the normal node pool is in the pending state and exceeds the 30s threshold, the WorkloadSpread controller will delete the pod to trigger pod reconstruction, and the new pod will be scheduled to the elastic node pool. During volume reduction, the pod on the elastic node is also preferentially reduced to save costs for users.

「3」Scatter to 3 zones, the scale is 1:1:3​

case-3

subsets:
- name: subset-a
maxReplicas: 20%
requiredNodeSelectorTerm:
matchExpressions:
- key: topology.kubernetes.io/zone
operator: In
values:
- zone-a
- name: subset-b
maxReplicas: 20%
requiredNodeSelectorTerm:
matchExpressions:
- key: topology.kubernetes.io/zone
operator: In
values:
- zone-b
- name: subset-c
maxReplicas: 60%
requiredNodeSelectorTerm:
matchExpressions:
- key: topology.kubernetes.io/zone
operator: In
values:
- zone-c

WorkloadSpread ensures that the pods are scheduled according to the defined proportion when scaling up and down.

「4」Configures different resource quotas on different CPU architecture​

case-4

subsets:
- name: subset-x86-arch
# maxReplicas...
# requiredNodeSelectorTerm...
patch:
metadata:
labels:
resource.cpu/arch: x86
spec:
containers:
- name: main
resources:
limits:
cpu: "500m"
memory: "800Mi"
- name: subset-arm-arch
# maxReplicas...
# requiredNodeSelectorTerm...
patch:
metadata:
labels:
resource.cpu/arch: arm
spec:
containers:
- name: main
resources:
limits:
cpu: "300m"
memory: "600Mi"

From the above example, we have patched different labels and container resources for the pods of two subsets, which is convenient for us to manage the pod more finely. When workload pods are distributed on nodes of different CPU architectures, configure different resource quotas to make better use of hardware resources.


Implementation​

WorkloadSpread is a pure bypass elastic/topology control solution. Users only need to create a corresponding WorkloadSpread config for their Deployment/Cloneset/Job/ReplicaSet Workloads. There is no need to change the them, and users will be no additional cost to use the WorkloadSpread.

arch

「1」 How to decide the priority when scaling up?​

Multiple subsets are defined in WorkloadSpread, and each subset represents a logical domain. Users can freely define subsets according to node configuration, hardware type, zone, etc. In particular, we defined the priority of subsets:

  • The priority is defined from high to low in the order from front to back, for example subset[i] has higher priority than subset[j] if i < j.

  • The pods will be scheduled to the subsets with higher priority first.

「2」 How to decide the priority when scaling down?​

Theoretically, the bypass solution of WorkloadSpread cannot interfere with the scaling logic in the workload controller.

However, this problem has been solved in the near future. Through the unremitting efforts (feedback) of users, k8s since version 1.21, it has been supported for ReplicaSet (deployment) to specify the "deletion cost" of the pods by setting the annotation controller.kubernetes.io/pod-deletion-cost: the higher the deletion cost, the lower the priority of deletion.

Since version v0.9.0 OpenKruise, the deletion cost feature has been supported in cloneset.

Therefore, the WorkloadSpread controller controls the scaling down order of the pods by adjusting their deletion cost.

For example, an WorkloadSpread associated a CloneSet with 10 replicas is as follows:

  subsets:
- name: subset-a
maxReplicas: 8
- name: subset-b

Then the deletion cost value and deletion order are as follows:

  • 8 pods in subset-a will have 200 deletion cost;
  • 2 pods in subset-b will have 100 deletion cost, and will be deleted first;

If user modify WorkloadSpread as:

  subsets:
- name: subset-a
maxReplicas: 5 # 8->5,
- name: subset-b

Then the deletion cost value and deletion order will also changed as follows:

  • 5 pods in subset-a will have 200 deletion cost;
  • 3 pods in subset-a will have -100 deletion cost, and will be deleted first;
  • 2 pods in subset-b will have 100 deletion cost;

In this way, workload can preferentially scale down those pods that exceed the subset maxReplicas limit.

「3」 How to solve the counting problems?​

How to ensure that webhook injects pod rules in strict accordance with the priority order of subset and the number of maxReplicas is a key problem at the implementation of WorkloadSpread.

3.1 solving concurrency consistency problem​

Sine there may be several kruise-controller-manager pods and lots of webhook Goroutines to process the same WorkloadSpread, the concurrency consistency problem must exist.

In the status of WorkloadSpread, there are the subsetStatuses field corresponding to each subset. The missingReplicas field in it indicates the number of pods required by the subset, and - 1 indicates that there is no quantity limit (subset.maxReplicas == nil).

spec:
subsets:
- name: subset-a
maxReplicas: 1
- name: subset-b
# ...
status:
subsetStatuses:
- name: subset-a
missingReplicas: 1
- name: subset-b
missingReplicas: -1
# ...

When webhook receives a pod create request:

  1. Find a suitable subset with missingReplicas greater than 0 or equals to -1 according to the subset order.
  2. After finding a suitable subset, if missingReplicas is greater than 0, subtract 1 first and try to update the WorkloadSpread status.
  3. If the update is successful, inject the rules defined by the subset into the pod.
  4. If the update fails, get the WorkloadSpread again to get the latest status, and return to step 1 (there is a certain limit on the number of retries).

Similarly, when webhook receives a pod delete or eviction request, MisingReplicas will add 1 to missingreplicas and update it.

There is no doubt that we are using optimistic locks to solve update conflicts. However, it is not appropriate to only use optimistic locks, because workload will create a large number of pods in parallel, and APIServer will send many pod create requests to webhook in an instant, resulting in a lot of conflicts in parallel processing. As we all know, optimistic lock is not suitable for too many conflicts, because the retry cost of solving conflicts is very high. To this end, we also added a WorkloadSpread level mutex to limit parallel processing to serial processing. There is a new problem in adding mutex locks, that is, after the current root obtains the lock, it is very likely that the WorkloadSpread obtained from infomer is not up-to-date, and will conflict as well. Therefore, after updating the WorkloadSpread, the Goroutine caches the latest WorkloadSpread and then releases the lock, so that the new Goroutine can directly get the latest WorkloadSpread from the cache after obtaining the lock. Of course, in the case of multiple webhooks, we still need to combine the optimistic lock mechanism to solve the conflict.

3.2 solving data consistency problem​

So, is the missingReplicas field controlled by the webhook? The answer is NO, because:

  1. The pod create request received by webhook may not really succeed in the end (for example, pod is illegal or fails in subsequent quota verification).

  2. The pod delete/eviction request received by webhook may not really succeed in the end (for example, it is intercepted by PDB, PUB, etc.).

  3. There are always various possibilities in k8s, leading to the end or disappearance of the pods without going through webhook (for example, phase enters succeeded/failed, or ETCD data is lost, etc.).

  4. At the same time, this is not in line with the end state oriented design concept.

Therefore, the WorkloadSpread status is controlled by webhook in collaboration with the controller:

  • Webhook requests link interception in pod create/delete/ eviction, and modifies the missingReplicas.

  • At the same time, the controller's reconcile will also get all pods under the current workload, classify them according to the subset, and update missingReplicas to the actual missing quantity.

  • From the above analysis, it is likely that there is a delay for the controller to obtain the pod from the informer, so we also added the creatingPods map in the status. When the pod is injected at webhook, the key will be recorded as pod name and value are timestamp to the map, and the controller maintains the real missingReplicas in combination with the map. Similarly, there is also a deleteingPods map to record the delete/eviction event of the pod.

「4」What to do if pod schedule fails?​

The configuration of reschedule strategy is supported in WorkloadSpread. By default, the type is fixed, that is, the pod is scheduled to the corresponding subset according to the sequence of each subset and the maxReplicas limit.

However, in real scenarios, many times, the resources of subset may not fully meet the number of maxReplicas due to some reasons, such as insufficient resources. Users need a more flexible reschedule strategy.

The adaptive capabilities provided by WorkloadSpread are logically divided into two types:

  1. SimulationSchedule: scheduling records exists in informer, so we want to simulate the scheduling of pods in webhook. That is, simple filtering is performed through nodeSelector/Affinity, Tolerances, and basic resources resources. (not applicable to virtual-kubelet)

  2. Reschedule: After scheduling the pod to a subset, if the scheduling failure exceeds the rescheduleCriticalSeconds time, mark the subset as unscheduled temporarily, and delete the pod to trigger reconstruction. By default, unscheduled will be reserved for 5min, that is, pod creation within 5min will skip this subset.


Conclusion​

WorkloadSpread combines some existing features of Kubernetes to give workload the ability of elastic and multi-domain deployment in the form of bypass. We hope that users can reduce workload deployment complexity by using WorkloadSpread and effectively reduce costs by taking advantage of its elastic scalability.

At present, WorkloadSpread is applied to some project in Alibaba, and adjustments in the use will be fed back to the community in time. In the future, there are some new capability plans for WorkloadSpread, such as managing the existing pods, supporting batch workloads, and even using label to match the pod across different workloads. Some of these capabilities need to actually consider the needs and scenarios of community users. I hope you can participate in kruise community, mention Issues and PRs, help users solve the problems of more cloud native deployment, and build a better community.


Reference​